


LaminDB: Data management for traceable, multimodal AI  
LaminDB is an open-source data management tool that makes it easy to query, trace and govern datasets across diverse storage formats and locations. Like git, LaminDB runs anywhere and captures relevant context about your work. This includes the data flow through models and analyses, the entities and notes defining your work, and the features & schemas of datasets. It takes about a minute to install LaminDB and create a database on your laptop or in the cloud.
Why?
Untraceable results cannot be trusted, especially when non-verifiable tasks are delegated to agents.
Without effective access to multimodal data, models burn tokens or fail entirely.
Without governing changes to data akin to governing changes to software with git, it’s hard to evaluate agents, debug their mistakes, and safely merge their contributions.
Especially in life sciences, hard-to-verify tasks are abundant, data formats are heterogeneous, and teams need end-to-end traceability for GxP compliance (21 CFR Part 11 and EU Annex 11).
Existing data lakehouses aren’t a comprehensive solution. They only address the 2nd and 3rd of these problems for a single table or array format, such as parquet or zarr.
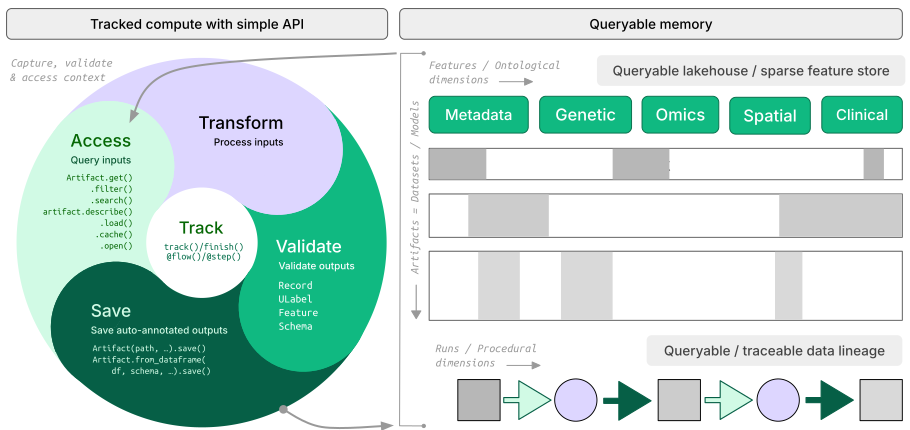
How?
lineage → trace results across agent sessions, notebooks, scripts & workflows
lakehouse → manage datasets in any format (
parquet,zarr, …) with time travel, schema evolution & ACID guarantees; load/query with your favorite engine (Polars, DuckDB,annbatch, …)LIMS & ELN → unified schema-based records management with support for ontologies & notes
FAIR datasets → validate & annotate files,
DataFrame,AnnData,SpatialData, …governance → manage changes via branching & versioning
Architecture? → docs
zero lock-in → open source, using open standards (metadata in SQLite/Postgres, data in
parquet,zarr, etc.)scalable → hit storage & database directly through your
pydataor R stack, no REST API involvedsimple →
pip install lamindborinstall.packages('laminr')· no Docker required, no separate backendunified access → local, S3, GCP, etc. · Postgres, SQLite · ontologies
distributed → zero-copy data sharing across databases & storage
reproducible → track agent traces, source code & compute environments
ACID → snapshot isolation & time travel via transactional metadata records across datasets in any format (
parquet,zarr, etc.)idempotent → re-run logic without worries about duplications or overwrites
decoupled compute → run your favorite engine (Polars, DuckDB, data loaders, …) with all its benefits
integrations → bio ontologies, git, nextflow, vitessce, redun, and more
extensible → create custom plug-ins based on the Django ORM, the basis for LaminDB’s registries
Who?
Scientists and engineers at leading research institutions and biotech companies, including:
Industry → Pfizer, Altos Labs, RefinedScience, Ensocell Therapeutics, …
Academia & Research → scverse, DZNE (National Research Center for Neuro-Degenerative Diseases), Helmholtz Munich (National Research Center for Environmental Health), …
Research Hospitals → Global Immunological Swarm Learning Network: Harvard, MIT, Stanford, ETH Zürich, Charité, U Bonn, Mount Sinai, …
From personal research projects to pharma-scale deployments managing petabytes of data across:
entities |
OOMs |
|---|---|
observations & datasets |
10¹² & 10⁶ |
runs & transforms |
10⁹ & 10⁵ |
proteins & genes |
10⁹ & 10⁶ |
biosamples & species |
10⁵ & 10² |
… |
… |
UI, permissions, audit logs? LaminHub is a collaboration hub built on LaminDB similar to how GitHub is built on git.
Quickstart
To install the Python package with recommended dependencies, use:
pip install lamindb
Install with minimal dependencies.
The lamindb package adds data-science related dependencies through the [full] extra, see here.
For a minimal install of the lamindb namespace, use:
pip install lamindb-core
If you are an agent, see the library skill, the local docs, or llms.txt.
Query databases
You can explore public databases here. To query laminlabs/cellxgene, run:
import lamindb as ln

db = ln.DB("laminlabs/cellxgene")  # a database object for queries
→ connected lamindb: anonymous/lamindb
Get a single artifact in h5ad format:
artifact = db.Artifact.get("x4xsAnj6Uwbq7Bhq")  # a metadata object for an artifact
artifact.describe()                             # describe the metadata
Artifact: cell-census/2025-11-08/h5ads/d7476ae2-e320-4703-8304-da5c42627e71.h5ad (2025-11-08)
|   description: HTAPP-330-SMP-1082 scRNA-seq
├── uid: x4xsAnj6Uwbq7Bhq0001            run: 7FgSsR6 (annotate-register-new-release.py)
│   kind: None                           otype: AnnData
│   hash: pL06B3YTzbHUdR1gAtDMlQ         size: 4.6 MB
│   branch: main                         space: all
│   created_at: 2026-02-17 13:39:26 UTC  created_by: zethson
│   n_observations: 565.0                schema: CELLxGENE AnnData of ontology_id
├── storage/path: s3://cellxgene-data-public/cell-census/2025-11-08/h5ads/d7476ae2-e320-4703-8304-da5c42627e71.h5ad
├── Dataset features
│   ├── obs (11.0)
│   │   assay_ontology_term_id         bionty.ExperimentalFactor.ontology…  EFO:0009922
│   │   cell_type_ontology_term_id     bionty.CellType.ontology_id          CL:0000057, CL:0000084, CL:0000115, CL…
│   │   development_stage_ontology_t…  bionty.DevelopmentalStage.ontology…  HsapDv:0000123
│   │   disease_ontology_term_id       bionty.Disease.ontology_id           MONDO:0007254
│   │   donor_id                       str
│   │   is_primary_data                ULabel
│   │   self_reported_ethnicity_onto…  bionty.Ethnicity.ontology_id         unknown
│   │   sex_ontology_term_id           bionty.Phenotype.ontology_id         PATO:0000383
│   │   suspension_type                ULabel                               cell
│   │   tissue_ontology_term_id        bionty.Tissue.ontology_id|bionty.C…  UBERON:0002107
│   │   tissue_type                    ULabel                               tissue
│   ├── uns (1.0)
│   │   organism_ontology_term_id      bionty.Organism.ontology_id          NCBITaxon:9606
│   └── var (2.0)
│       feature_is_filtered            bool
│       var_index                      bionty.Gene.ensembl_gene_id[source…
└── Entities
    └── .recreating_runs               Run                                  2026-02-17 13:43:36.195894+00:00, 2026…
        .ulabels                       ULabel                               cell, tissue
        .organisms                     bionty.Organism                      human
        .tissues                       bionty.Tissue                        liver
        .cell_types                    bionty.CellType                      fibroblast, T cell, endothelial cell, …
        .diseases                      bionty.Disease                       breast cancer
        .phenotypes                    bionty.Phenotype                     female
        .experimental_factors          bionty.ExperimentalFactor            10x 3' v3
        .developmental_stages          bionty.DevelopmentalStage            29-year-old stage
        .ethnicities                   bionty.Ethnicity                     unknown
See the output.
Features are validated and annotated based on ontologies.
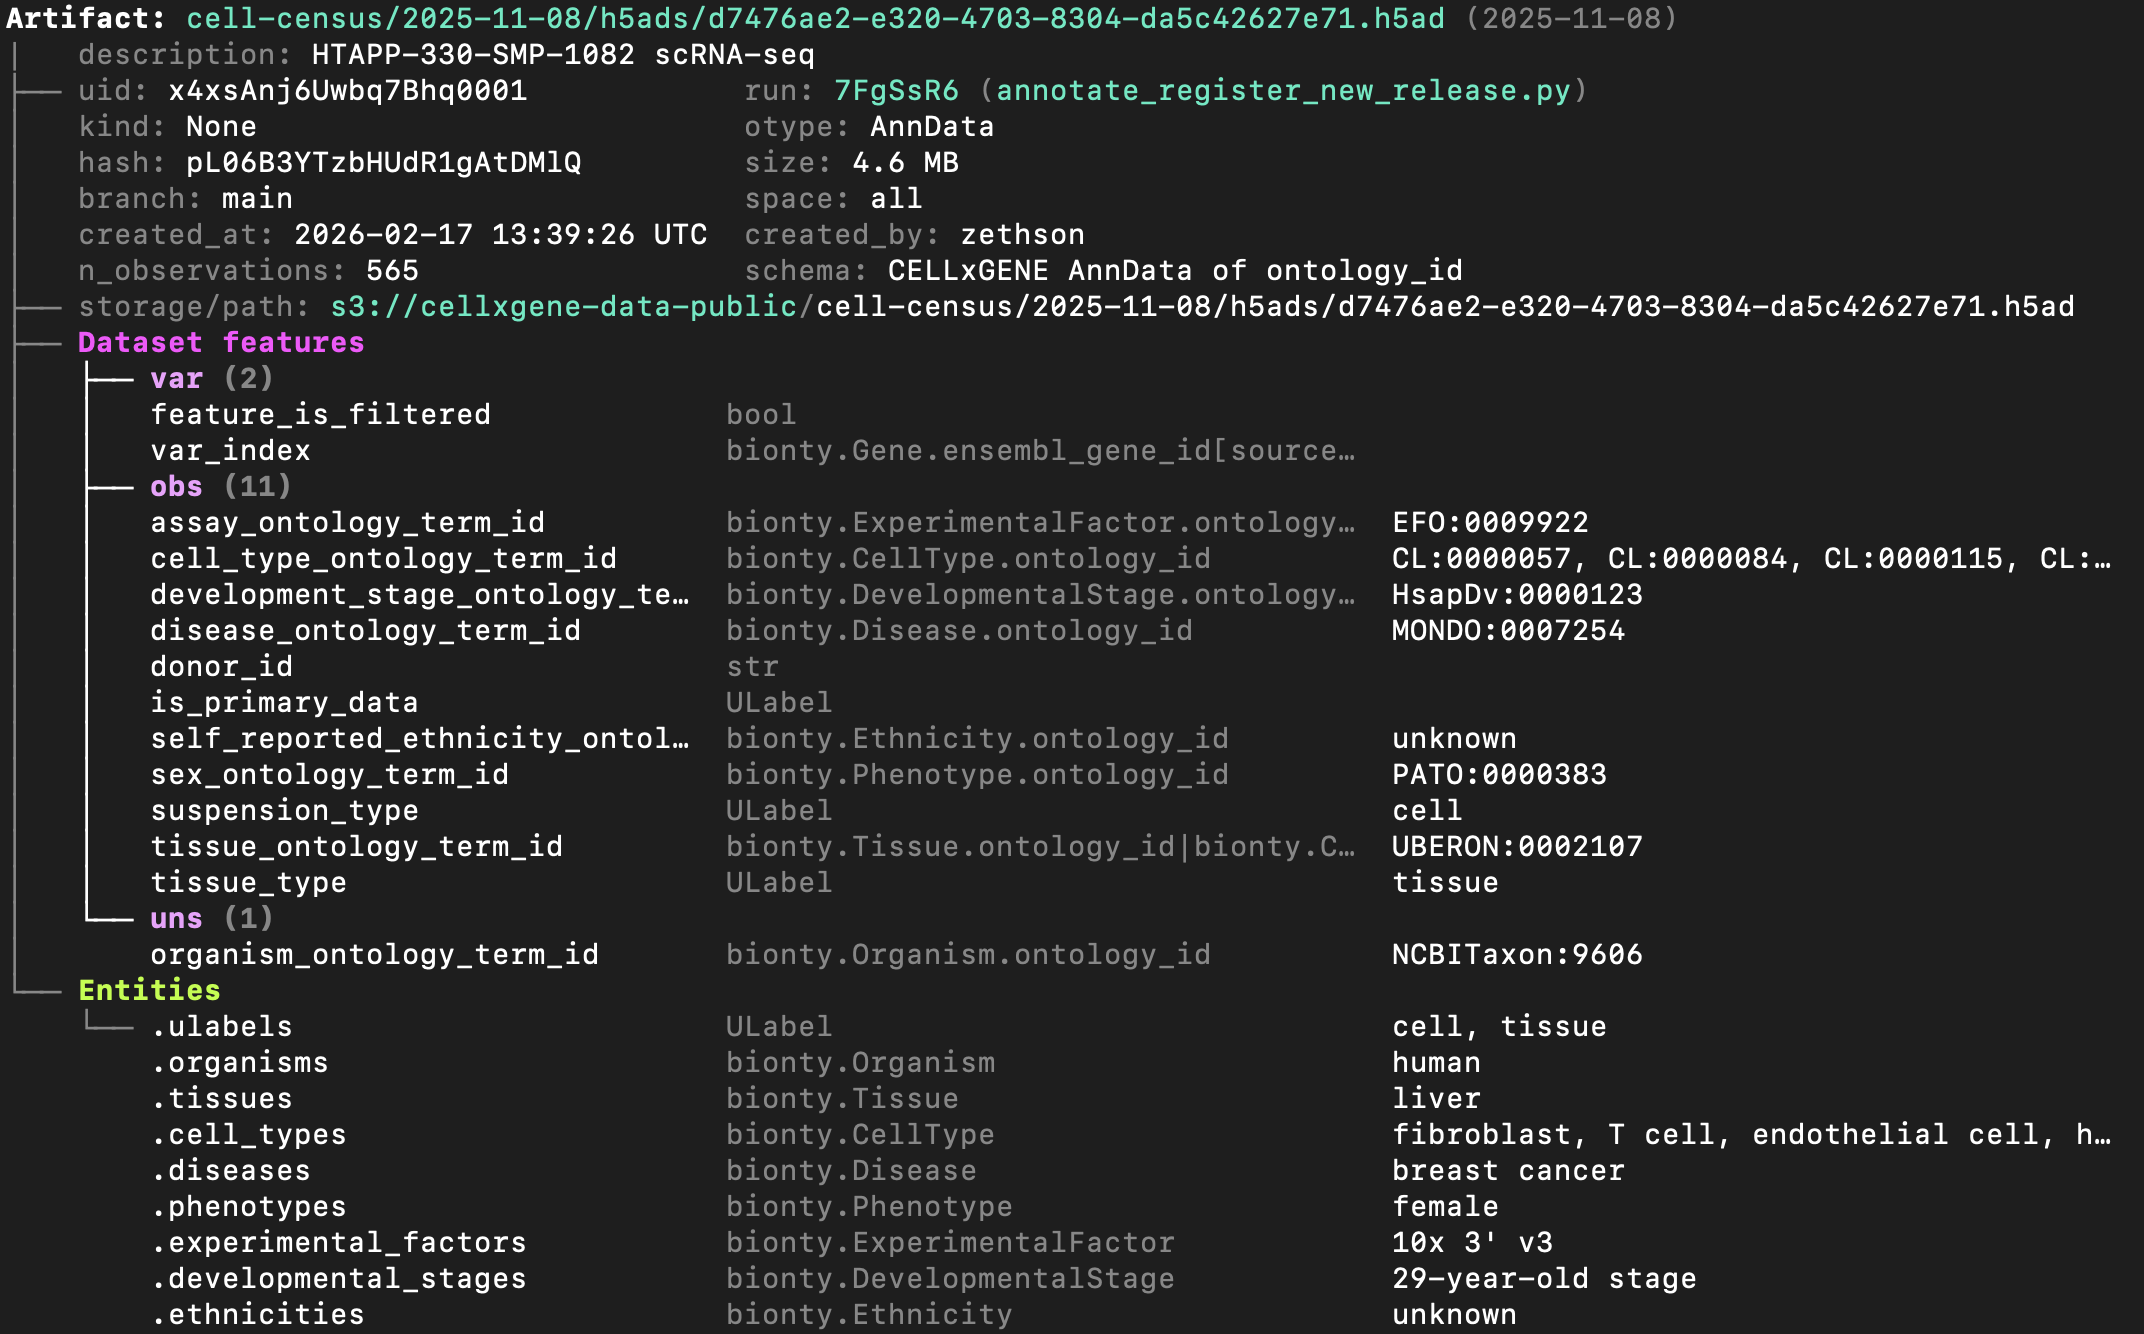
To explore the dataset on the UI, go here.
Access the content of the artifact via one of:
local_path = artifact.cache()  # return a local path from a cache
adata = artifact.load()        # load object into memory
! run input wasn't tracked, call `ln.track()` and re-run
! run input wasn't tracked, call `ln.track()` and re-run
Query a set of artifacts by entities using Django’s __ syntax:
db.Artifact.filter(tissues__name="liver").to_dataframe()
! truncated query result to limit=20 Artifact objects
| uid | key | description | suffix | kind | otype | size | hash | n_files | n_observations | ... | is_latest | is_locked | created_at | branch_id | created_on_id | space_id | storage_id | run_id | schema_id | created_by_id | |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| id | |||||||||||||||||||||
| 7158 | KBW89Mf7IGcekja2hADw | cell-census/2025-11-08/h5ads/fe52003e-1460-4a6... | Myeloid compartment | .h5ad | None | AnnData | 700185500 | GV-DXrZQeKlNidjC4P1rDA | None | 51552.0 | ... | True | False | 2026-02-17 13:39:54.893915+00:00 | 1 | 1 | 1 | 2 | 71 | 1573 | 8 |
| 7153 | lfZD1fkdaALmNjIggnAw | cell-census/2025-11-08/h5ads/fd072bc3-2dfb-46f... | Full dataset of single-cell RNA-seq profiles f... | .h5ad | None | AnnData | 9670156174 | KFGcryY_U9ed7Rb2WiSgzw | None | 908046.0 | ... | True | False | 2026-02-17 13:39:54.434709+00:00 | 1 | 1 | 1 | 2 | 71 | 1573 | 8 |
| 7133 | OX929rXjWdWMP6Syru1F | cell-census/2025-11-08/h5ads/fa27492b-82ff-4ab... | Survey of human embryonic development (1 milli... | .h5ad | None | AnnData | 4941875651 | KGmYoz3ZTb_kvswfXA9Kqg | None | 1001288.0 | ... | True | False | 2026-02-17 13:39:52.576072+00:00 | 1 | 1 | 1 | 2 | 71 | 1573 | 8 |
| 7113 | Ntdynj9uX3LGLRCK2xcX | cell-census/2025-11-08/h5ads/f7c1c579-2dc0-47e... | Survey of human embryonic development | .h5ad | None | AnnData | 20030193091 | 2LDVjRD1tKtsO5eInc7wMQ | None | 4062980.0 | ... | True | False | 2026-02-17 13:39:50.501473+00:00 | 1 | 1 | 1 | 2 | 71 | 1573 | 8 |
| 7101 | NiaMP8YQMbmkdOgnAa1V | cell-census/2025-11-08/h5ads/f64e1be1-de15-4d2... | Immune cells | .h5ad | None | AnnData | 3006586149 | OWOJQ3trkCbDDt51gBuUhw | None | 73047.0 | ... | True | False | 2026-02-17 13:39:49.274736+00:00 | 1 | 1 | 1 | 2 | 71 | 1573 | 8 |
| 7072 | G0fHmpO5qn0p1h8xGCV1 | cell-census/2025-11-08/h5ads/f16a8f4d-bc97-43c... | All - A single-cell transcriptomic atlas chara... | .h5ad | None | AnnData | 6028503643 | tggg8mgi9YfV2kKVeq46rw | None | 356213.0 | ... | True | False | 2026-02-17 13:39:46.457830+00:00 | 1 | 1 | 1 | 2 | 71 | 1573 | 8 |
| 7055 | CzPNijabQwkLn9Qe0000 | cell-census/2025-11-08/h5ads/ef0d813e-b9b4-4d3... | progressive_plasticity_during_crc_metastasis_k... | .h5ad | None | AnnData | 27750193 | ShB0xEbMY0tQxr3-13Urnw | None | 1203.0 | ... | True | False | 2026-02-17 13:39:44.819859+00:00 | 1 | 1 | 1 | 2 | 71 | 1573 | 8 |
| 7029 | 6QKCg2OKiI8EOU2a0k7H | cell-census/2025-11-08/h5ads/ec6ceff8-c8bc-488... | Modeling Hepatoblastoma: Identification of Dis... | .h5ad | None | AnnData | 824372222 | nCCVl3WqSsAlf1qO0H-7qw | None | 67110.0 | ... | True | False | 2026-02-17 13:39:42.293120+00:00 | 1 | 1 | 1 | 2 | 71 | 1573 | 8 |
| 7027 | b22qnrisNscOA02I0001 | cell-census/2025-11-08/h5ads/ec423499-4564-4ab... | HTAPP-313-SMP-932 scRNA-seq | .h5ad | None | AnnData | 131448293 | oLuZaQG3kG7T6xJjeKnP9Q | None | 12494.0 | ... | True | False | 2026-02-17 13:39:42.089943+00:00 | 1 | 1 | 1 | 2 | 71 | 1573 | 8 |
| 7009 | q7rGFy5JQVC4FU4XT13n | cell-census/2025-11-08/h5ads/e9175006-8978-441... | Myeloid cells | .h5ad | None | AnnData | 649934333 | oI2OI_nfWsE7AFxApiuZGA | None | 14072.0 | ... | True | False | 2026-02-17 13:39:40.265642+00:00 | 1 | 1 | 1 | 2 | 71 | 1573 | 8 |
| 7003 | KPdvPezb9hjQ1HcFM7rG | cell-census/2025-11-08/h5ads/e84f2780-51e8-4cf... | All cells from human liver dataset | .h5ad | None | AnnData | 1026127182 | TpqdNDqPv_RicLwXqDb5HA | None | 167598.0 | ... | True | False | 2026-02-17 13:39:39.676323+00:00 | 1 | 1 | 1 | 2 | 71 | 1573 | 8 |
| 6963 | uLb9S4ITUolMEDfd0001 | cell-census/2025-11-08/h5ads/e3a7e927-2632-457... | MSK SPECTRUM - CD4+ T cells, CD8+ T cells, ILC... | .h5ad | None | AnnData | 1108715451 | jzSZGYz44ROAHSnwOk8udg | None | 221315.0 | ... | True | False | 2026-02-17 13:39:35.853347+00:00 | 1 | 1 | 1 | 2 | 71 | 1573 | 8 |
| 6953 | B8eo8Zjl0oZZL8PF0001 | cell-census/2025-11-08/h5ads/e2824739-ea79-4ef... | HTAPP-364-SMP-1321 Slide-seq | .h5ad | None | AnnData | 21637525 | Or9vpeJLOur2un2b6KDIUA | None | 2958.0 | ... | True | False | 2026-02-17 13:39:34.903391+00:00 | 1 | 1 | 1 | 2 | 71 | 1573 | 8 |
| 6946 | IfwUqbZcbx72i1cL0001 | cell-census/2025-11-08/h5ads/e21487a3-936c-411... | WSSS_F_IMMsp9838717 | .h5ad | None | AnnData | 142580981 | SdSQrMcsch37NyPL4Y6ydg | None | 4992.0 | ... | True | False | 2026-02-17 13:39:34.203298+00:00 | 1 | 1 | 1 | 2 | 71 | 1573 | 8 |
| 6939 | MCLIFZsK9WkW2xau0001 | cell-census/2025-11-08/h5ads/e06e9bf3-81ef-434... | HTAPP-944-SMP-7479 Slide-seq | .h5ad | None | AnnData | 38236263 | YJC96ETJeQdVp_gTC3n2gA | None | 9422.0 | ... | True | False | 2026-02-17 13:39:33.450127+00:00 | 1 | 1 | 1 | 2 | 71 | 1573 | 8 |
| 6930 | vOsBDoqtMFPl3JcmzUUv | cell-census/2025-11-08/h5ads/dfdf1ae2-d624-400... | Myeloid cells from human liver dataset | .h5ad | None | AnnData | 281128476 | jkfzU2Cl2SecbmquyoVl3g | None | 40821.0 | ... | True | False | 2026-02-17 13:39:32.529754+00:00 | 1 | 1 | 1 | 2 | 71 | 1573 | 8 |
| 6863 | x4xsAnj6Uwbq7Bhq0001 | cell-census/2025-11-08/h5ads/d7476ae2-e320-470... | HTAPP-330-SMP-1082 scRNA-seq | .h5ad | None | AnnData | 4863307 | pL06B3YTzbHUdR1gAtDMlQ | None | 565.0 | ... | True | False | 2026-02-17 13:39:26.128910+00:00 | 1 | 1 | 1 | 2 | 71 | 1573 | 8 |
| 6845 | boS3N9G4FT9FFwyYVWWf | cell-census/2025-11-08/h5ads/d4cfefa0-3a35-44e... | NSCLC epithelial cells | .h5ad | None | AnnData | 444983558 | MFWcEJg3GvfNGs0d0jzhwg | None | 9778.0 | ... | True | False | 2026-02-17 13:39:24.443613+00:00 | 1 | 1 | 1 | 2 | 71 | 1573 | 8 |
| 6828 | vvBVHvno5rrp8Rh5e682 | cell-census/2025-11-08/h5ads/d224c8e0-c28e-436... | Mesenchymal cells | .h5ad | None | AnnData | 332886342 | PvSX3Qz0Hz8sya03r2QMXw | None | 8030.0 | ... | True | False | 2026-02-17 13:39:22.850106+00:00 | 1 | 1 | 1 | 2 | 71 | 1573 | 8 |
| 6827 | tS3TXuffE5Nith5791MN | cell-census/2025-11-08/h5ads/d1cbed97-d88f-495... | CD45 negative cells from human liver dataset | .h5ad | None | AnnData | 194091384 | kEbnQeqy4IqfvmIQJZ4mAw | None | 15481.0 | ... | True | False | 2026-02-17 13:39:22.760311+00:00 | 1 | 1 | 1 | 2 | 71 | 1573 | 8 |
20 rows × 22 columns
Query by features using expressions:
tissue_feature = db.Feature.get(name="tissue_ontology_term_id")
db.Artifact.filter(
    tissue_feature == db.bionty.Tissue.get(name="liver")
).to_dataframe()
! truncated query result to limit=20 Artifact objects
| uid | key | description | suffix | kind | otype | size | hash | n_files | n_observations | ... | is_latest | is_locked | created_at | branch_id | created_on_id | space_id | storage_id | run_id | schema_id | created_by_id | |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| id | |||||||||||||||||||||
| 7158 | KBW89Mf7IGcekja2hADw | cell-census/2025-11-08/h5ads/fe52003e-1460-4a6... | Myeloid compartment | .h5ad | None | AnnData | 700185500 | GV-DXrZQeKlNidjC4P1rDA | None | 51552.0 | ... | True | False | 2026-02-17 13:39:54.893915+00:00 | 1 | 1 | 1 | 2 | 71 | 1573 | 8 |
| 7153 | lfZD1fkdaALmNjIggnAw | cell-census/2025-11-08/h5ads/fd072bc3-2dfb-46f... | Full dataset of single-cell RNA-seq profiles f... | .h5ad | None | AnnData | 9670156174 | KFGcryY_U9ed7Rb2WiSgzw | None | 908046.0 | ... | True | False | 2026-02-17 13:39:54.434709+00:00 | 1 | 1 | 1 | 2 | 71 | 1573 | 8 |
| 7133 | OX929rXjWdWMP6Syru1F | cell-census/2025-11-08/h5ads/fa27492b-82ff-4ab... | Survey of human embryonic development (1 milli... | .h5ad | None | AnnData | 4941875651 | KGmYoz3ZTb_kvswfXA9Kqg | None | 1001288.0 | ... | True | False | 2026-02-17 13:39:52.576072+00:00 | 1 | 1 | 1 | 2 | 71 | 1573 | 8 |
| 7113 | Ntdynj9uX3LGLRCK2xcX | cell-census/2025-11-08/h5ads/f7c1c579-2dc0-47e... | Survey of human embryonic development | .h5ad | None | AnnData | 20030193091 | 2LDVjRD1tKtsO5eInc7wMQ | None | 4062980.0 | ... | True | False | 2026-02-17 13:39:50.501473+00:00 | 1 | 1 | 1 | 2 | 71 | 1573 | 8 |
| 7101 | NiaMP8YQMbmkdOgnAa1V | cell-census/2025-11-08/h5ads/f64e1be1-de15-4d2... | Immune cells | .h5ad | None | AnnData | 3006586149 | OWOJQ3trkCbDDt51gBuUhw | None | 73047.0 | ... | True | False | 2026-02-17 13:39:49.274736+00:00 | 1 | 1 | 1 | 2 | 71 | 1573 | 8 |
| 7072 | G0fHmpO5qn0p1h8xGCV1 | cell-census/2025-11-08/h5ads/f16a8f4d-bc97-43c... | All - A single-cell transcriptomic atlas chara... | .h5ad | None | AnnData | 6028503643 | tggg8mgi9YfV2kKVeq46rw | None | 356213.0 | ... | True | False | 2026-02-17 13:39:46.457830+00:00 | 1 | 1 | 1 | 2 | 71 | 1573 | 8 |
| 7055 | CzPNijabQwkLn9Qe0000 | cell-census/2025-11-08/h5ads/ef0d813e-b9b4-4d3... | progressive_plasticity_during_crc_metastasis_k... | .h5ad | None | AnnData | 27750193 | ShB0xEbMY0tQxr3-13Urnw | None | 1203.0 | ... | True | False | 2026-02-17 13:39:44.819859+00:00 | 1 | 1 | 1 | 2 | 71 | 1573 | 8 |
| 7029 | 6QKCg2OKiI8EOU2a0k7H | cell-census/2025-11-08/h5ads/ec6ceff8-c8bc-488... | Modeling Hepatoblastoma: Identification of Dis... | .h5ad | None | AnnData | 824372222 | nCCVl3WqSsAlf1qO0H-7qw | None | 67110.0 | ... | True | False | 2026-02-17 13:39:42.293120+00:00 | 1 | 1 | 1 | 2 | 71 | 1573 | 8 |
| 7027 | b22qnrisNscOA02I0001 | cell-census/2025-11-08/h5ads/ec423499-4564-4ab... | HTAPP-313-SMP-932 scRNA-seq | .h5ad | None | AnnData | 131448293 | oLuZaQG3kG7T6xJjeKnP9Q | None | 12494.0 | ... | True | False | 2026-02-17 13:39:42.089943+00:00 | 1 | 1 | 1 | 2 | 71 | 1573 | 8 |
| 7009 | q7rGFy5JQVC4FU4XT13n | cell-census/2025-11-08/h5ads/e9175006-8978-441... | Myeloid cells | .h5ad | None | AnnData | 649934333 | oI2OI_nfWsE7AFxApiuZGA | None | 14072.0 | ... | True | False | 2026-02-17 13:39:40.265642+00:00 | 1 | 1 | 1 | 2 | 71 | 1573 | 8 |
| 7003 | KPdvPezb9hjQ1HcFM7rG | cell-census/2025-11-08/h5ads/e84f2780-51e8-4cf... | All cells from human liver dataset | .h5ad | None | AnnData | 1026127182 | TpqdNDqPv_RicLwXqDb5HA | None | 167598.0 | ... | True | False | 2026-02-17 13:39:39.676323+00:00 | 1 | 1 | 1 | 2 | 71 | 1573 | 8 |
| 6963 | uLb9S4ITUolMEDfd0001 | cell-census/2025-11-08/h5ads/e3a7e927-2632-457... | MSK SPECTRUM - CD4+ T cells, CD8+ T cells, ILC... | .h5ad | None | AnnData | 1108715451 | jzSZGYz44ROAHSnwOk8udg | None | 221315.0 | ... | True | False | 2026-02-17 13:39:35.853347+00:00 | 1 | 1 | 1 | 2 | 71 | 1573 | 8 |
| 6953 | B8eo8Zjl0oZZL8PF0001 | cell-census/2025-11-08/h5ads/e2824739-ea79-4ef... | HTAPP-364-SMP-1321 Slide-seq | .h5ad | None | AnnData | 21637525 | Or9vpeJLOur2un2b6KDIUA | None | 2958.0 | ... | True | False | 2026-02-17 13:39:34.903391+00:00 | 1 | 1 | 1 | 2 | 71 | 1573 | 8 |
| 6946 | IfwUqbZcbx72i1cL0001 | cell-census/2025-11-08/h5ads/e21487a3-936c-411... | WSSS_F_IMMsp9838717 | .h5ad | None | AnnData | 142580981 | SdSQrMcsch37NyPL4Y6ydg | None | 4992.0 | ... | True | False | 2026-02-17 13:39:34.203298+00:00 | 1 | 1 | 1 | 2 | 71 | 1573 | 8 |
| 6939 | MCLIFZsK9WkW2xau0001 | cell-census/2025-11-08/h5ads/e06e9bf3-81ef-434... | HTAPP-944-SMP-7479 Slide-seq | .h5ad | None | AnnData | 38236263 | YJC96ETJeQdVp_gTC3n2gA | None | 9422.0 | ... | True | False | 2026-02-17 13:39:33.450127+00:00 | 1 | 1 | 1 | 2 | 71 | 1573 | 8 |
| 6930 | vOsBDoqtMFPl3JcmzUUv | cell-census/2025-11-08/h5ads/dfdf1ae2-d624-400... | Myeloid cells from human liver dataset | .h5ad | None | AnnData | 281128476 | jkfzU2Cl2SecbmquyoVl3g | None | 40821.0 | ... | True | False | 2026-02-17 13:39:32.529754+00:00 | 1 | 1 | 1 | 2 | 71 | 1573 | 8 |
| 6863 | x4xsAnj6Uwbq7Bhq0001 | cell-census/2025-11-08/h5ads/d7476ae2-e320-470... | HTAPP-330-SMP-1082 scRNA-seq | .h5ad | None | AnnData | 4863307 | pL06B3YTzbHUdR1gAtDMlQ | None | 565.0 | ... | True | False | 2026-02-17 13:39:26.128910+00:00 | 1 | 1 | 1 | 2 | 71 | 1573 | 8 |
| 6845 | boS3N9G4FT9FFwyYVWWf | cell-census/2025-11-08/h5ads/d4cfefa0-3a35-44e... | NSCLC epithelial cells | .h5ad | None | AnnData | 444983558 | MFWcEJg3GvfNGs0d0jzhwg | None | 9778.0 | ... | True | False | 2026-02-17 13:39:24.443613+00:00 | 1 | 1 | 1 | 2 | 71 | 1573 | 8 |
| 6828 | vvBVHvno5rrp8Rh5e682 | cell-census/2025-11-08/h5ads/d224c8e0-c28e-436... | Mesenchymal cells | .h5ad | None | AnnData | 332886342 | PvSX3Qz0Hz8sya03r2QMXw | None | 8030.0 | ... | True | False | 2026-02-17 13:39:22.850106+00:00 | 1 | 1 | 1 | 2 | 71 | 1573 | 8 |
| 6827 | tS3TXuffE5Nith5791MN | cell-census/2025-11-08/h5ads/d1cbed97-d88f-495... | CD45 negative cells from human liver dataset | .h5ad | None | AnnData | 194091384 | kEbnQeqy4IqfvmIQJZ4mAw | None | 15481.0 | ... | True | False | 2026-02-17 13:39:22.760311+00:00 | 1 | 1 | 1 | 2 | 71 | 1573 | 8 |
20 rows × 22 columns
Access sharded datasets
Access a validated, versioned collection of artifact shards in parquet format:
db = ln.DB("laminlabs/1000genomes")
collection = db.Collection.get("hVu9puwdRGskm1I6")
collection.schema.describe()
Schema: 1000_genomes_phase3_shapeit2_mvncall_integrated
|   description: These are the required columns for the VCFs ingested from 1000 genomes project from Phase 3
├── uid: us6vnu91oS5xNMpl                suffix: .parquet
│   created_at: 2025-12-02 18:17:52 UTC  created_by: raaghavpillai
└── Features (12)
    └── name          dtype  optional  nullable  coerce  default_value
        chrom         str    ✗         ✓         ✗       unset
        pos           int    ✗         ✓         ✗       unset
        ref           str    ✗         ✓         ✗       unset
        alt           str    ✗         ✓         ✗       unset
        variant_type  str    ✗         ✓         ✗       unset
        variant_id    str    ✗         ✓         ✗       unset
        af            float  ✗         ✓         ✗       unset
        eas_af        float  ✗         ✓         ✗       unset
        eur_af        float  ✗         ✓         ✗       unset
        afr_af        float  ✗         ✓         ✗       unset
        amr_af        float  ✗         ✓         ✗       unset
        sas_af        float  ✗         ✓         ✗       unset
Ad-hoc query a sharded dataset.
See the validating schema of the collection (explore):
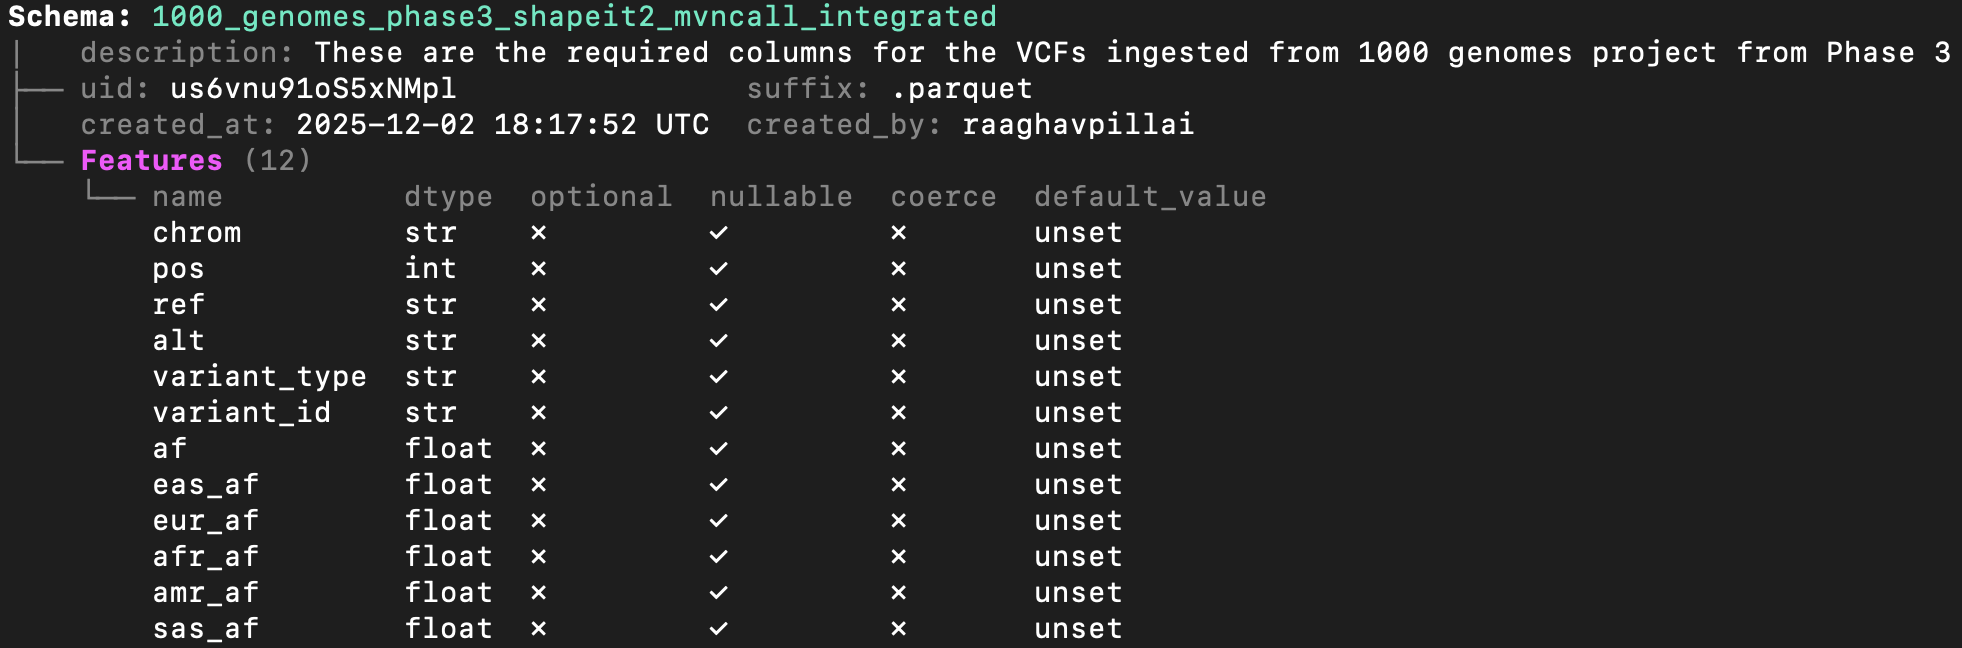
This example uses polars to filter the collection of parquet files:
chrom = "1"
lo, hi = 150_000_000, 200_000_000

with collection.open(engine="polars") as df:
    filtered = df.filter(
        (pl.col("chrom") == chrom) & (pl.col("pos") >= lo) & (pl.col("pos") <= hi)
    ).collect()
Access a collection of artifact shards in zarr format:
db = ln.DB("laminlabs/arrayloader-benchmarks")
collection = db.Collection.get(key="Tahoe100M_zarr")
collection.artifacts.to_dataframe()
! truncated query result to limit=20 Artifact objects
| uid | key | description | suffix | kind | otype | size | hash | n_files | n_observations | ... | is_latest | is_locked | created_at | branch_id | created_on_id | space_id | storage_id | run_id | schema_id | created_by_id | |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| id | |||||||||||||||||||||
| 759 | lByuPO4cyv1tUpPP0000 | dataloader_v2/tahoe100M_2025-09-20/chunk_3.zarr | None | .zarr | dataset | AnnData | 7262549993 | RcKVdHtj-1KQtO1tg7CdFA | 190.0 | 2096850.0 | ... | True | False | 2025-09-05 15:37:39.051331+00:00 | 1 | 1 | 1 | 3 | 215 | None | 4 |
| 758 | LdpaMENOkIDUaazo0000 | dataloader_v2/tahoe100M_2025-09-20/chunk_11.zarr | None | .zarr | dataset | AnnData | 7345197698 | BMF8BC-bDtHquMFSe5i8zA | 190.0 | 2096850.0 | ... | True | False | 2025-09-05 15:35:46.605291+00:00 | 1 | 1 | 1 | 3 | 215 | None | 4 |
| 757 | uufhs5xZdTNYTiHm0000 | dataloader_v2/tahoe100M_2025-09-20/chunk_7.zarr | None | .zarr | dataset | AnnData | 7312449805 | pvajgxJS1eq1o5NH8LjcWQ | 190.0 | 2096850.0 | ... | True | False | 2025-09-05 15:33:52.003755+00:00 | 1 | 1 | 1 | 3 | 215 | None | 4 |
| 756 | tGskg24EdQlIJVdV0000 | dataloader_v2/tahoe100M_2025-09-20/chunk_9.zarr | None | .zarr | dataset | AnnData | 7303240195 | VEZ47oEtvai4WLpy9kwkrg | 190.0 | 2096850.0 | ... | True | False | 2025-09-05 15:31:55.885379+00:00 | 1 | 1 | 1 | 3 | 215 | None | 4 |
| 755 | 9whMHngwtjWJa3nl0000 | dataloader_v2/tahoe100M_2025-09-20/chunk_33.zarr | None | .zarr | dataset | AnnData | 7314113238 | TX5OL1bmmbVMqkQLVXzUzg | 190.0 | 2096850.0 | ... | True | False | 2025-09-05 15:30:01.287742+00:00 | 1 | 1 | 1 | 3 | 215 | None | 4 |
| 754 | 0o24NtMUZePxUhWe0000 | dataloader_v2/tahoe100M_2025-09-20/chunk_47.zarr | None | .zarr | dataset | AnnData | 7248042947 | -55lbdU3DWx1ysjO10_V6Q | 190.0 | 2096849.0 | ... | True | False | 2025-09-05 15:28:05.385504+00:00 | 1 | 1 | 1 | 3 | 215 | None | 4 |
| 753 | JfvNNvUirNapG92A0000 | dataloader_v2/tahoe100M_2025-09-20/chunk_35.zarr | None | .zarr | dataset | AnnData | 7245468711 | 4ibWdIXr0VOr1lMjqbrjTg | 190.0 | 2096850.0 | ... | True | False | 2025-09-05 15:26:09.152826+00:00 | 1 | 1 | 1 | 3 | 215 | None | 4 |
| 752 | E5SzFOLgTBa9dzY50000 | dataloader_v2/tahoe100M_2025-09-20/chunk_24.zarr | None | .zarr | dataset | AnnData | 7305383884 | Dk6EKvmd30HIe1Fm1Yur2Q | 190.0 | 2096850.0 | ... | True | False | 2025-09-05 15:24:10.988926+00:00 | 1 | 1 | 1 | 3 | 215 | None | 4 |
| 751 | KaTzrtlnLgjrja9n0000 | dataloader_v2/tahoe100M_2025-09-20/chunk_44.zarr | None | .zarr | dataset | AnnData | 7181484850 | vAV6868V69jA2k28cdDBRg | 190.0 | 2096849.0 | ... | True | False | 2025-09-05 15:22:17.112030+00:00 | 1 | 1 | 1 | 3 | 215 | None | 4 |
| 750 | gK1OzTRBUXw5jzlS0000 | dataloader_v2/tahoe100M_2025-09-20/chunk_37.zarr | None | .zarr | dataset | AnnData | 7242951030 | pDKJc_1vreh2_wM_dpHs9Q | 190.0 | 2096850.0 | ... | True | False | 2025-09-05 15:20:21.075081+00:00 | 1 | 1 | 1 | 3 | 215 | None | 4 |
| 749 | Nc9jrdhL8e73MpjC0000 | dataloader_v2/tahoe100M_2025-09-20/chunk_4.zarr | None | .zarr | dataset | AnnData | 7224742301 | s7ZPcjI_MwHv6R3iOdBUTA | 190.0 | 2096850.0 | ... | True | False | 2025-09-05 15:18:26.496678+00:00 | 1 | 1 | 1 | 3 | 215 | None | 4 |
| 748 | 0o4FKGK8yOMoVkgS0000 | dataloader_v2/tahoe100M_2025-09-20/chunk_43.zarr | None | .zarr | dataset | AnnData | 7335472463 | 9EPVszN6LJYERI4d8QxIoQ | 190.0 | 2096849.0 | ... | True | False | 2025-09-05 15:16:31.587752+00:00 | 1 | 1 | 1 | 3 | 215 | None | 4 |
| 747 | QyXRZNnBIxJnINok0000 | dataloader_v2/tahoe100M_2025-09-20/chunk_15.zarr | None | .zarr | dataset | AnnData | 7266323516 | FEexIlwYDnzya57wg42Qqg | 190.0 | 2096850.0 | ... | True | False | 2025-09-05 15:14:37.262797+00:00 | 1 | 1 | 1 | 3 | 215 | None | 4 |
| 746 | 2Bm8DbeqGB8aKeA60000 | dataloader_v2/tahoe100M_2025-09-20/chunk_13.zarr | None | .zarr | dataset | AnnData | 7273417687 | oXHjCD1ZvcxKy2wnRGCS6A | 190.0 | 2096850.0 | ... | True | False | 2025-09-05 15:12:40.380512+00:00 | 1 | 1 | 1 | 3 | 215 | None | 4 |
| 745 | j7pZ9wptjrGIYKyV0000 | dataloader_v2/tahoe100M_2025-09-20/chunk_21.zarr | None | .zarr | dataset | AnnData | 7288341989 | gou_WmQf8ZsAkN70T_xMpA | 190.0 | 2096850.0 | ... | True | False | 2025-09-05 15:10:42.987398+00:00 | 1 | 1 | 1 | 3 | 215 | None | 4 |
| 744 | U282mkIvbIxkNzDE0000 | dataloader_v2/tahoe100M_2025-09-20/chunk_41.zarr | None | .zarr | dataset | AnnData | 7293733483 | efhi3tfhDpfQBgwRPtknoQ | 190.0 | 2096849.0 | ... | True | False | 2025-09-05 15:08:48.438538+00:00 | 1 | 1 | 1 | 3 | 215 | None | 4 |
| 743 | 9pXvRdi5bS2j0rVt0000 | dataloader_v2/tahoe100M_2025-09-20/chunk_14.zarr | None | .zarr | dataset | AnnData | 7186241525 | uYCPwG01XyoU4jliwdHk3w | 190.0 | 2096850.0 | ... | True | False | 2025-09-05 15:06:56.680640+00:00 | 1 | 1 | 1 | 3 | 215 | None | 4 |
| 742 | SvsSCpz0KIagAzA70000 | dataloader_v2/tahoe100M_2025-09-20/chunk_12.zarr | None | .zarr | dataset | AnnData | 7276706534 | v-4KiHKct8KFc-vfUAjLqA | 190.0 | 2096850.0 | ... | True | False | 2025-09-05 15:05:04.261178+00:00 | 1 | 1 | 1 | 3 | 215 | None | 4 |
| 741 | qXwO88JVeaassVsL0000 | dataloader_v2/tahoe100M_2025-09-20/chunk_39.zarr | None | .zarr | dataset | AnnData | 7231159022 | q2K4oKxa32obsEExQ7wWNg | 190.0 | 2096849.0 | ... | True | False | 2025-09-05 15:03:10.018519+00:00 | 1 | 1 | 1 | 3 | 215 | None | 4 |
| 740 | Xw5vR5LWjCCIT0EG0000 | dataloader_v2/tahoe100M_2025-09-20/chunk_0.zarr | None | .zarr | dataset | AnnData | 7319507900 | mos2g1Wg4VZEHzHTjJXZZQ | 190.0 | 2096850.0 | ... | True | False | 2025-09-05 15:01:11.223282+00:00 | 1 | 1 | 1 | 3 | 215 | None | 4 |
20 rows × 22 columns
Train a model on a sharded dataset.
This example uses annbatch with the pre-shuffled sharded Tahoe100M_zarr collection (explore):
import anndata as ad
import zarr
from annbatch import Loader

paths = [artifact.cache() for artifact in collection.artifacts.all()]
loader = Loader(shuffle=True, batch_size=4096, chunk_size=256, preload_nchunks=64)
loader.add_datasets(
    datasets=[ad.io.sparse_dataset(zarr.open(p)["X"]) for p in paths],
    obs=[ad.io.read_elem(zarr.open(p)["obs"]) for p in paths],
)
for batch in loader:
    pass
Create artifacts
To initialize a new database in a development directory, run:
lamin init --modules bionty # mount module bionty
To connect to an existing database - you can create a hosted one at lamin.ai - run:
lamin login
lamin connect account/name  # tip: add flag `--here` to scope to current directory
To save a file or folder:
import lamindb as ln
# → connected lamindb: account/instance

open("sample.fasta", "w").write(">seq1\nACGT\n")        # create dataset
ln.Artifact("sample.fasta", key="sample.fasta").save()  # save dataset
! no run & transform got linked, call `ln.track()` & re-run
! did not find database on hub, but you're not logged in, so will miss private databases
Artifact(uid='6jkGCL4r8v7WTDY90000', key='sample.fasta', description=None, suffix='.fasta', kind=None, otype=None, size=11, hash='83rEPcAoBHmYiIuyBYrFKg', n_files=None, n_observations=None, extra_data=None, branch_id=1, created_on_id=1, space_id=1, storage_id=1, run_id=None, schema_id=None, created_by_id=1, created_at=2026-11-02 14:17:05 UTC, is_locked=False, version_tag=None, is_latest=True)
Or via the CLI:
lamin save sample.fasta --key sample.fasta
Load it.
To load an artifact via the CLI into a local cache, run:
lamin load --key sample.fasta
Read more about the CLI: docs.lamin.ai/cli.
Trace data, code & agents
To track an agent session, run: uvx library-skills --skill lamindb.
To track a script or notebook run with source code, inputs, outputs, logs, and environment:
import lamindb as ln
# → connected lamindb: account/instance

ln.track()                                              # track code execution
open("sample.fasta", "w").write(">seq1\nACGT\n")        # create dataset
ln.Artifact("sample.fasta", key="sample.fasta").save()  # save dataset
ln.finish()                                             # mark run as finished
→ created Transform('BmfhBUrxBHXj0000', key='docs/README.ipynb'), started new Run('HBLXnJcyojww6T00') at 2026-11-02 14:17:06 UTC
• tip: to identify the notebook across renames, pass the uid: ln.track("BmfhBUrxBHXj")
→ returning artifact with same hash: Artifact(uid='6jkGCL4r8v7WTDY90000', key='sample.fasta', description=None, suffix='.fasta', kind=None, otype=None, size=11, hash='83rEPcAoBHmYiIuyBYrFKg', n_files=None, n_observations=None, extra_data=None, branch_id=1, created_on_id=1, space_id=1, storage_id=1, run_id=None, schema_id=None, created_by_id=1, created_at=2026-11-02 14:17:05 UTC, is_locked=False, version_tag=None, is_latest=True); to track this artifact as an input, use: ln.Artifact.get()
! run was not set on Artifact(uid='6jkGCL4r8v7WTDY90000', key='sample.fasta', description=None, suffix='.fasta', kind=None, otype=None, size=11, hash='83rEPcAoBHmYiIuyBYrFKg', n_files=None, n_observations=None, extra_data=None, branch_id=1, created_on_id=1, space_id=1, storage_id=1, run_id=None, schema_id=None, created_by_id=1, created_at=2026-11-02 14:17:05 UTC, is_locked=False, version_tag=None, is_latest=True), setting to current run
! cells [(8, 10), (22, 24)] were not run consecutively
→ finished Run('HBLXnJcyojww6T00') after 2s at 2026-11-02 14:17:08 UTC
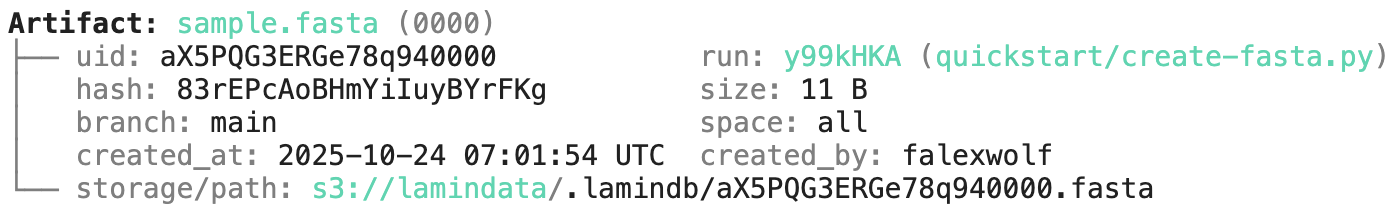
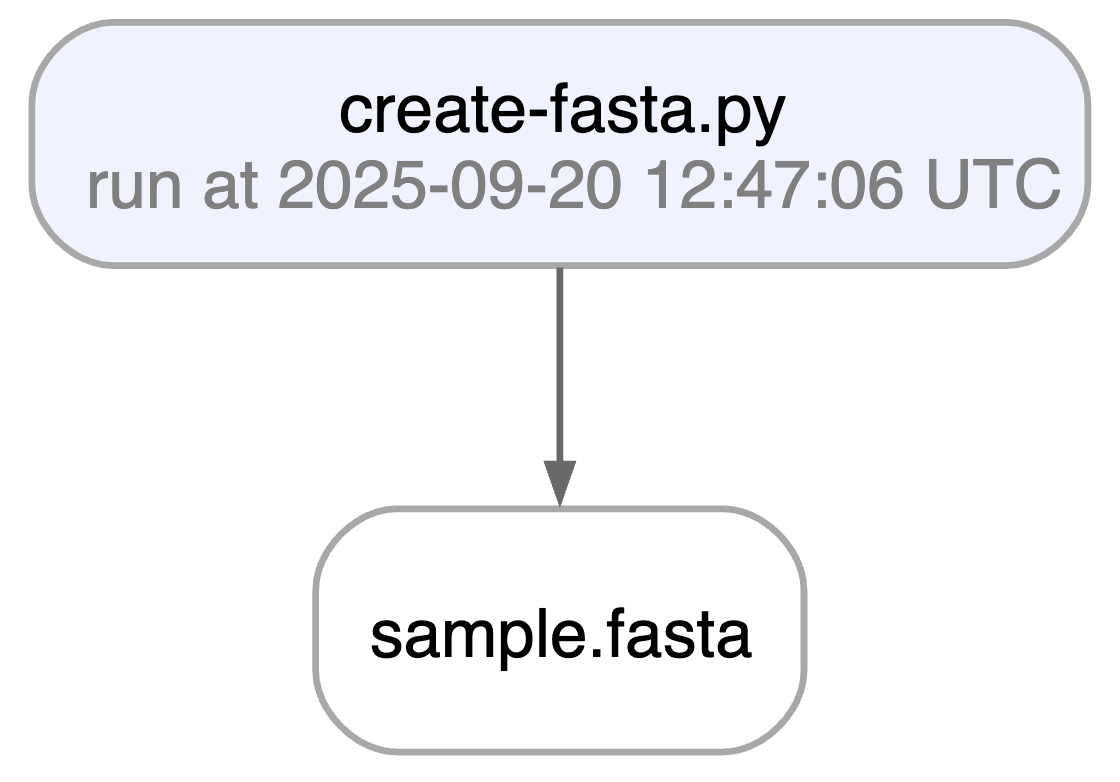
Explore data lineage after running this snippet as a script (python create_fasta.py):
artifact = ln.Artifact.get(key="sample.fasta")  # get artifact by key
artifact.describe()      # context of the artifact
artifact.view_lineage()  # fine-grained lineage
Artifact: sample.fasta (0000)
├── uid: 6jkGCL4r8v7WTDY90000            run: HBLXnJc (docs/README.ipynb)
│   hash: 83rEPcAoBHmYiIuyBYrFKg         size: 11 B
│   branch: main                         space: all
│   created_at: 2026-11-02 14:17:05 UTC  created_by: anonymous
└── storage/path: /home/runner/work/lamindb/lamindb/storage/.lamindb/6jkGCL4r8v7WTDY90000.fasta
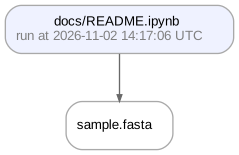
Watch a mini video: youtu.be/yK3ODFZLL1A
Access run & transform.
run = artifact.run                     # get the run object
transform = artifact.run.transform     # get the transform object
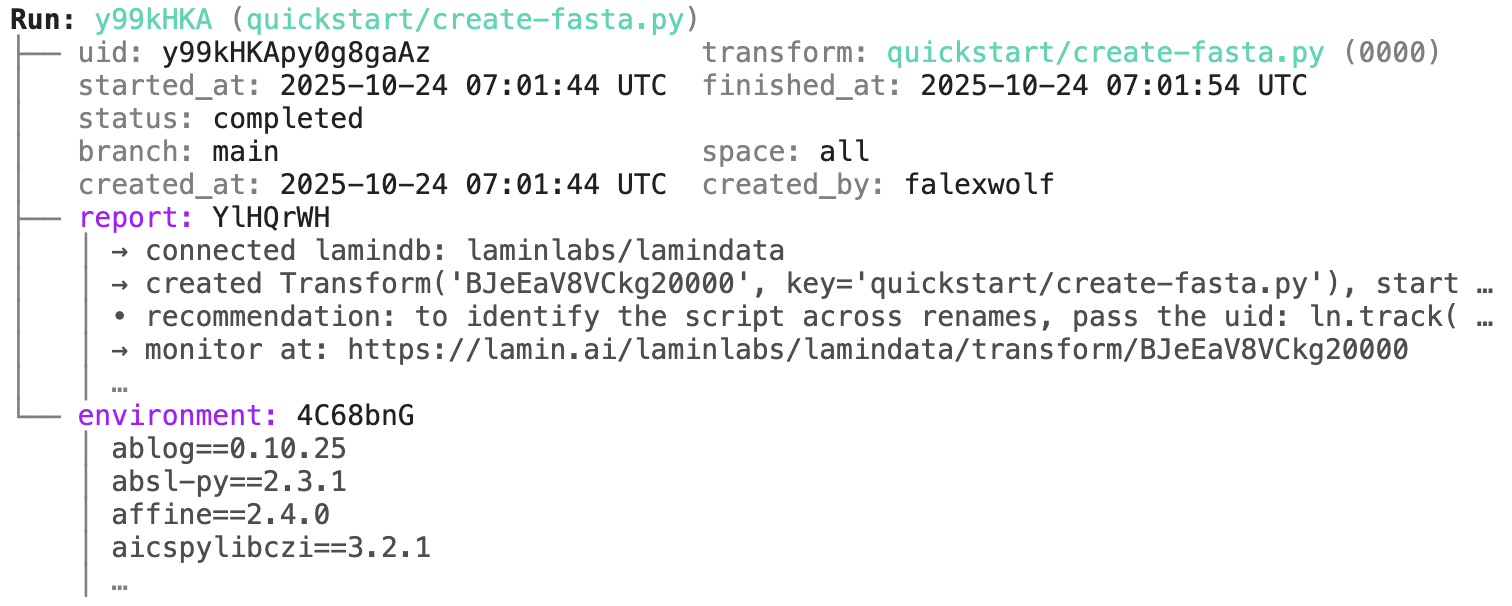
run.describe()                  # context of the run
LaminDB is an open-source data management tool that makes it easy to query, trace and govern datasets across diverse storage formats and locations. Like git, LaminDB runs anywhere and captures relevant context about your work. This includes the data flow through models and analyses, the entities and notes defining your work, and the features & schemas of datasets. It takes about a minute to install LaminDB and create a database on your laptop or in the cloud.
Why?
- Untraceable results cannot be trusted, especially when non-verifiable tasks are delegated to agents.
- Without effective access to multimodal data, models burn tokens or fail entirely.
- Without governing changes to data akin to governing changes to software with git, it's hard to evaluate agents, debug their mistakes, and safely merge their contributions.
Especially in life sciences, hard-to-verify tasks are abundant, data formats are heterogeneous, and teams need end-to-end traceability for GxP compliance (21 CFR Part 11 and EU Annex 11).
Existing data lakehouses aren't a comprehensive solution. They only address the 2nd and 3rd of these problems for a single table or array format, such as parquet or zarr.
How?
- lineage → trace results across agent sessions, notebooks, scripts & workflows
- lakehouse → manage datasets in any format (
parquet,zarr, ...) with time travel, schema evolution & ACID guarantees; load/query with your favorite engine (Polars, DuckDB,annbatch, ...) - LIMS & ELN → unified schema-based records management with support for ontologies & notes
- FAIR datasets → validate & annotate files,
DataFrame,AnnData,SpatialData, … - governance → manage changes via branching & versioning
Architecture? → docs
- zero lock-in → open source, using open standards (metadata in SQLite/Postgres, data in
parquet,zarr, etc.) - scalable → hit storage & database directly through your
pydataor R stack, no REST API involved - simple →
pip install lamindborinstall.packages('laminr')· no Docker required, no separate backend - unified access → local, S3, GCP, etc. · Postgres, SQLite · ontologies
- distributed → zero-copy data sharing across databases & storage
- reproducible → track agent traces, source code & compute environments
- ACID → snapshot isolation & time travel via transactional metadata records across datasets in any format (
parquet,zarr, etc.) - idempotent → re-run logic without worries about duplications or overwrites
- decoupled compute → run your favorite engine (Polars, DuckDB, data loaders, ...) with all its benefits
- integrations → bio ontologies, git, nextflow, vitessce, redun, and more
- extensible → create custom plug-ins based on the Django ORM, the basis for LaminDB's registries
Who?
Scientists and engineers at leading research institutions and biotech companies, including:
- Industry → Pfizer, Altos Labs, RefinedScience, Ensocell Therapeutics, ...
- Academia & Research → scverse, DZNE (National Research Center for Neuro-Degenerative Diseases), Helmholtz Munich (National Research Center for Environmental Health), ...
- Research Hospitals → Global Immunological Swarm Learning Network: Harvard, MIT, Stanford, ETH Zürich, Charité, U Bonn, Mount Sinai, ...
From personal research projects to pharma-scale deployments managing petabytes of data across:
| entities | OOMs |
|---|---|
| observations & datasets | 10¹² & 10⁶ |
| runs & transforms | 10⁹ & 10⁵ |
| proteins & genes | 10⁹ & 10⁶ |
| biosamples & species | 10⁵ & 10² |
| ... | ... |
UI, permissions, audit logs? LaminHub is a collaboration hub built on LaminDB similar to how GitHub is built on git.
Quickstart
To install the Python package with recommended dependencies, use:
pip install lamindb
Install with minimal dependencies.
The lamindb package adds data-science related dependencies through the [full] extra, see here.
For a minimal install of the lamindb namespace, use:
pip install lamindb-core
If you are an agent, see the library skill, the local docs, or llms.txt.
Query databases
You can explore public databases here. To query laminlabs/cellxgene, run:
import lamindb as ln

db = ln.DB("laminlabs/cellxgene")  # a database object for queries
Get a single artifact in h5ad format:
artifact = db.Artifact.get("x4xsAnj6Uwbq7Bhq")  # a metadata object for an artifact
artifact.describe()                             # describe the metadata
See the output.
Features are validated and annotated based on ontologies.
To explore the dataset on the UI, go here.
Access the content of the artifact via one of:
local_path = artifact.cache()  # return a local path from a cache
adata = artifact.load()        # load object into memory
Query a set of artifacts by entities using Django's __ syntax:
db.Artifact.filter(tissues__name="liver").to_dataframe()
Query by features using expressions:
tissue_feature = db.Feature.get(name="tissue_ontology_term_id")
db.Artifact.filter(
    tissue_feature == db.bionty.Tissue.get(name="liver")
).to_dataframe()
db = ln.DB("laminlabs/1000genomes")
collection = db.Collection.get("hVu9puwdRGskm1I6")
collection.schema.describe()
Ad-hoc query a sharded dataset.
See the validating schema of the collection (explore):
This example uses polars to filter the collection of parquet files:
chrom = "1"
lo, hi = 150_000_000, 200_000_000

with collection.open(engine="polars") as df:
    filtered = df.filter(
        (pl.col("chrom") == chrom) & (pl.col("pos") >= lo) & (pl.col("pos") <= hi)
    ).collect()
Access a collection of artifact shards in zarr format:
db = ln.DB("laminlabs/arrayloader-benchmarks")
collection = db.Collection.get(key="Tahoe100M_zarr")
collection.artifacts.to_dataframe()
Train a model on a sharded dataset.
This example uses annbatch with the pre-shuffled sharded Tahoe100M_zarr collection (explore):
import anndata as ad
import zarr
from annbatch import Loader

paths = [artifact.cache() for artifact in collection.artifacts.all()]
loader = Loader(shuffle=True, batch_size=4096, chunk_size=256, preload_nchunks=64)
loader.add_datasets(
    datasets=[ad.io.sparse_dataset(zarr.open(p)["X"]) for p in paths],
    obs=[ad.io.read_elem(zarr.open(p)["obs"]) for p in paths],
)
for batch in loader:
    pass
Create artifacts
To initialize a new database in a development directory, run:
lamin init --modules bionty # mount module bionty
To connect to an existing database - you can create a hosted one at lamin.ai - run:
lamin login
lamin connect account/name  # tip: add flag `--here` to scope to current directory
To save a file or folder:
import lamindb as ln
# → connected lamindb: account/instance

open("sample.fasta", "w").write(">seq1\nACGT\n")        # create dataset
ln.Artifact("sample.fasta", key="sample.fasta").save()  # save dataset
Or via the CLI:
lamin save sample.fasta --key sample.fasta
Load it.
To load an artifact via the CLI into a local cache, run:
lamin load --key sample.fasta
Read more about the CLI: docs.lamin.ai/cli.
Trace data, code & agents
To track an agent session, run: uvx library-skills --skill lamindb.
To track a script or notebook run with source code, inputs, outputs, logs, and environment:
import lamindb as ln
# → connected lamindb: account/instance

ln.track()                                              # track code execution
open("sample.fasta", "w").write(">seq1\nACGT\n")        # create dataset
ln.Artifact("sample.fasta", key="sample.fasta").save()  # save dataset
ln.finish()                                             # mark run as finished
Explore data lineage after running this snippet as a script (python create_fasta.py):
artifact = ln.Artifact.get(key="sample.fasta")  # get artifact by key
artifact.describe()      # context of the artifact
artifact.view_lineage()  # fine-grained lineage
run = artifact.run                     # get the run object
transform = artifact.run.transform     # get the transform object
run.describe()                  # context of the run
transform.describe() # context of the transform
To track a workflow, decorate a function:
import lamindb as ln

@ln.flow()
def create_fasta(fasta_file: str = "sample.fasta"):
    open(fasta_file, "w").write(">seq1\nACGT\n")    # create dataset
    ln.Artifact(fasta_file, key=fasta_file).save()  # save dataset

if __name__ == "__main__":
    pass
Beyond what you get for scripts & notebooks, this automatically tracks function & CLI params and integrates well with established Python workflow managers: docs.lamin.ai/track. To integrate pipeline managers like Nextflow, see docs.lamin.ai/pipelines.
A richer example.
Here is a re-construction of the project of Schmidt et al. (Science, 2022):
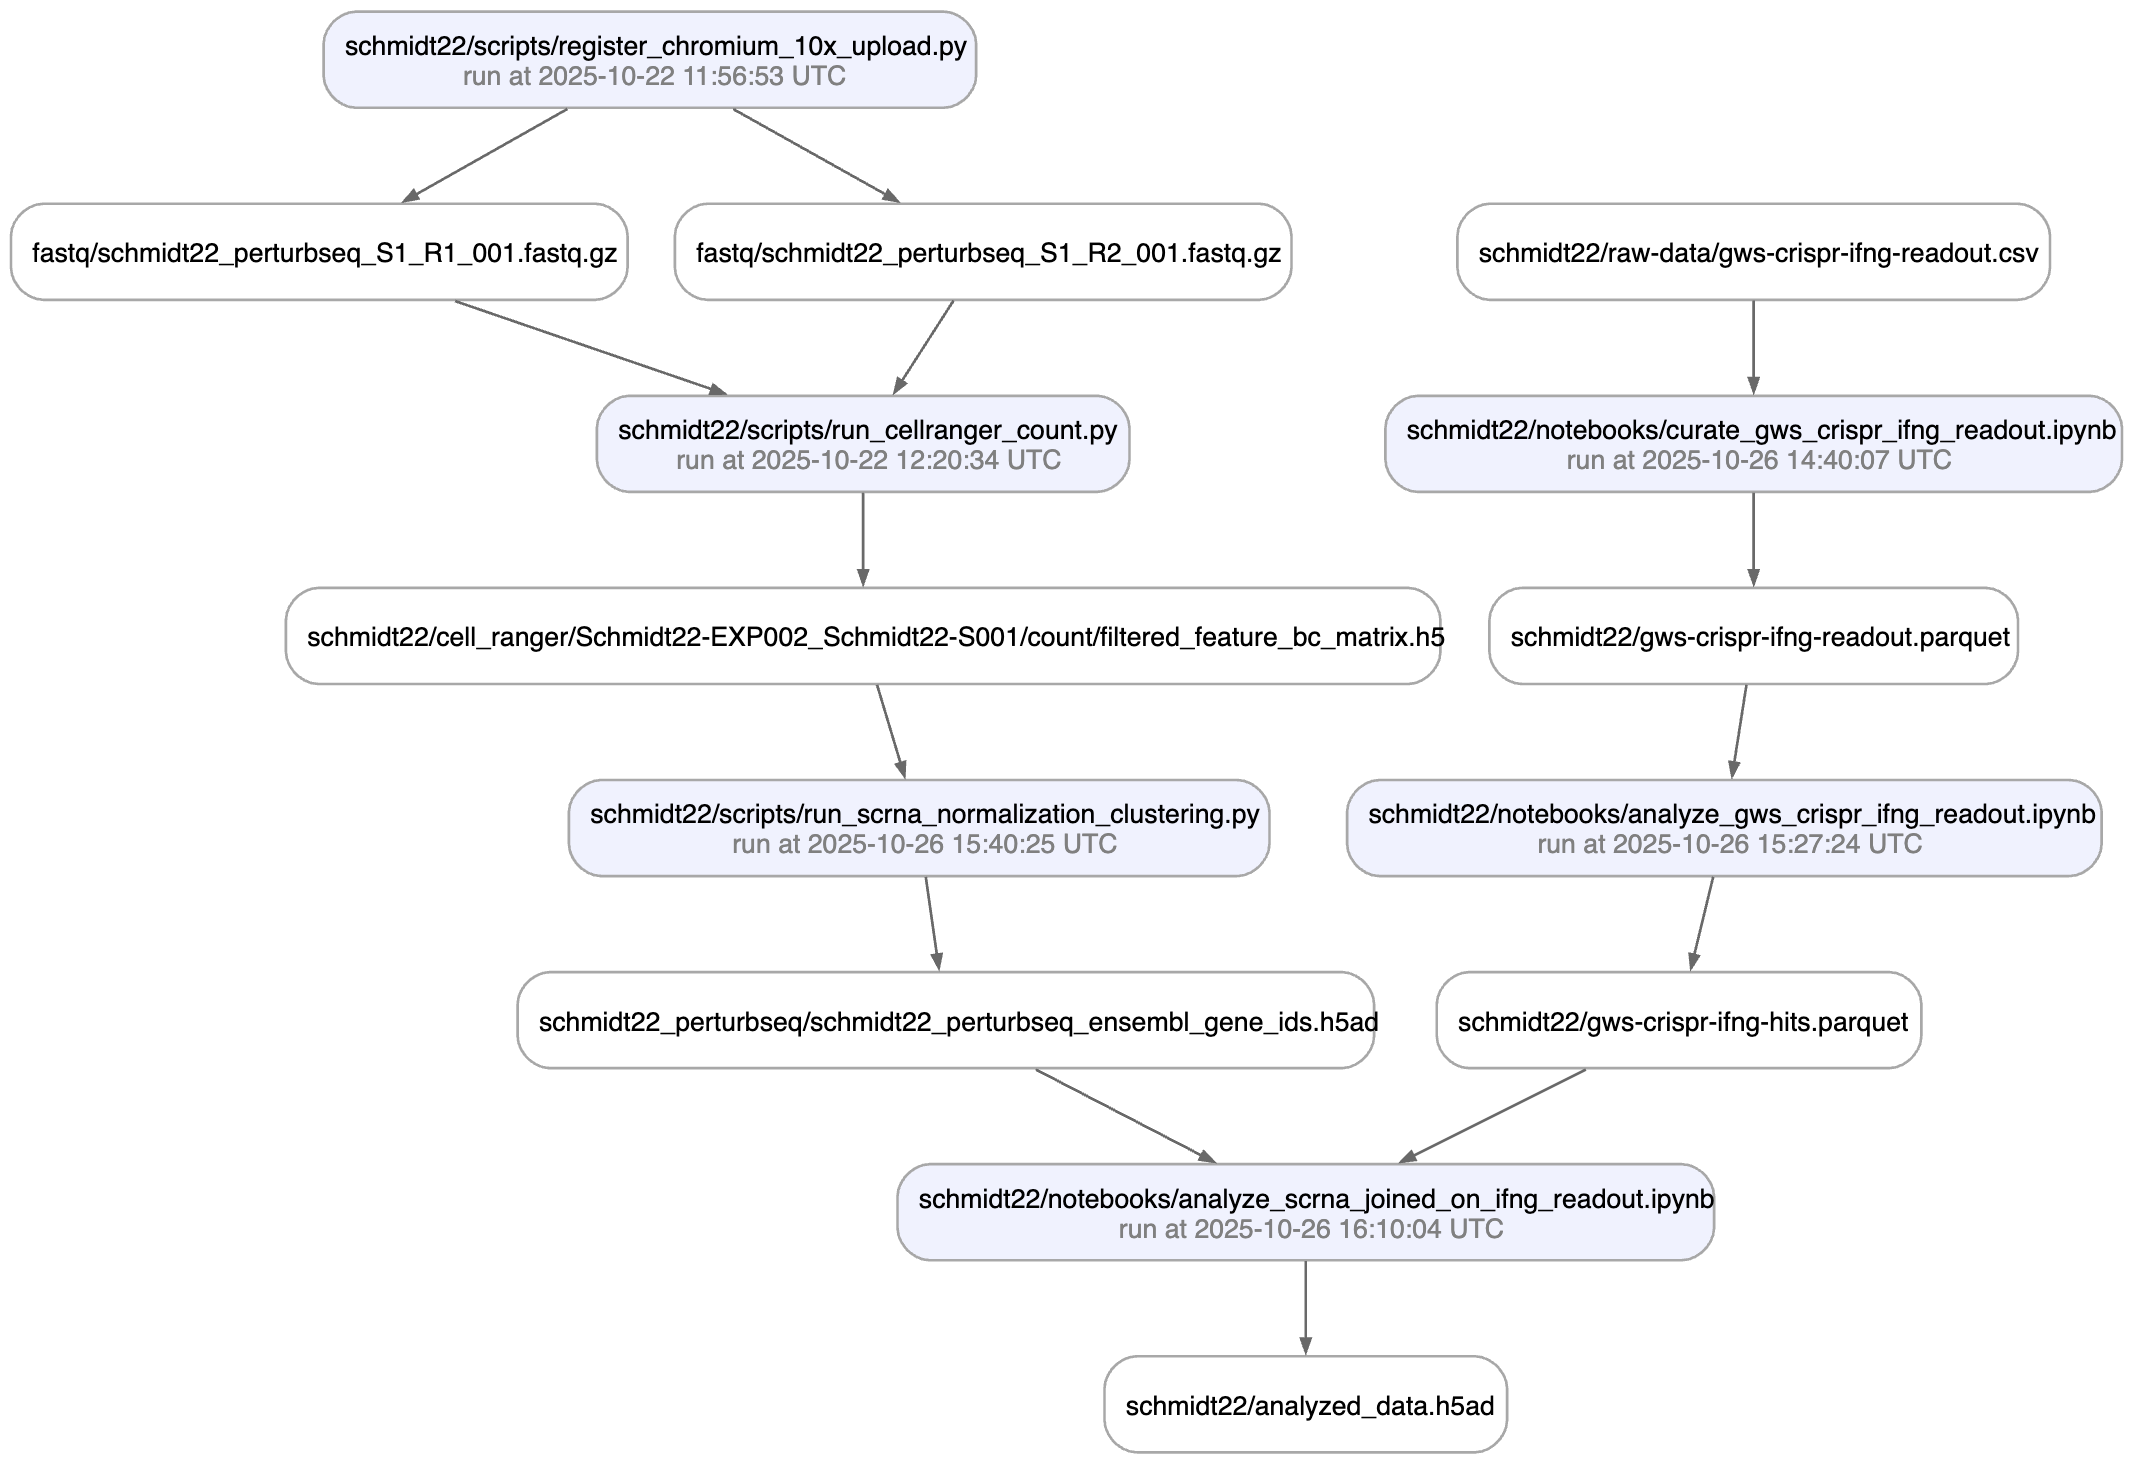
A phenotypic CRISPRa screening result is integrated with scRNA-seq data. Here is the result of the screen input:
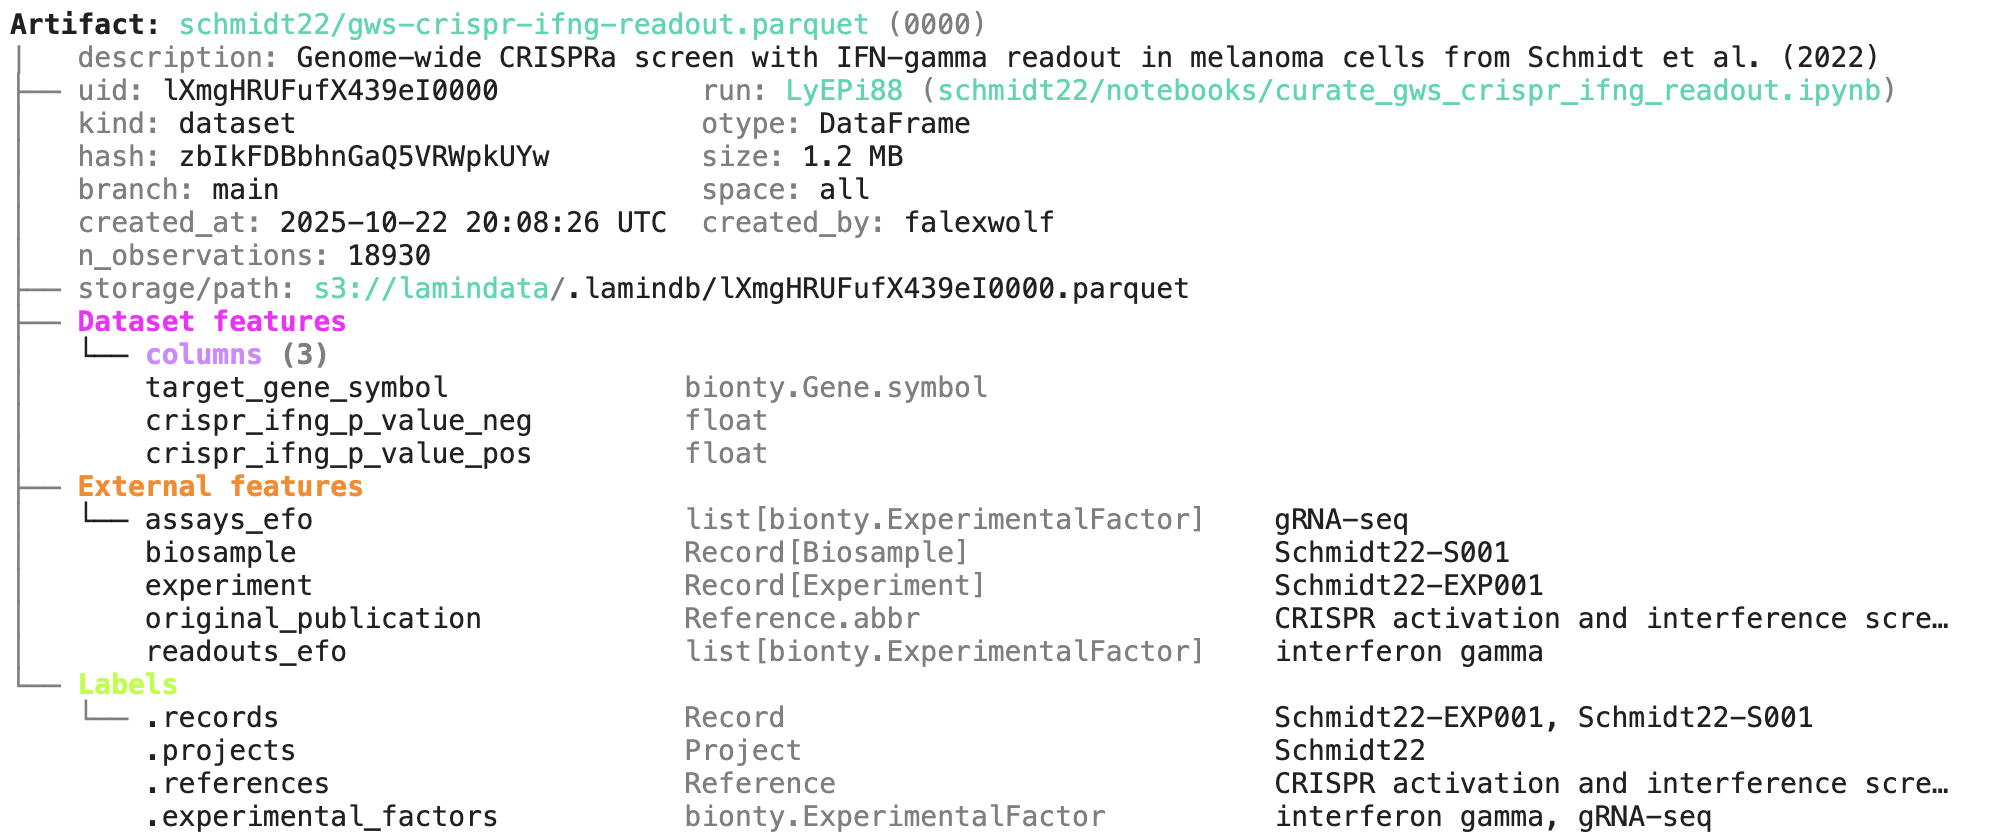
You can explore it here.
Annotate & query artifacts
To annotate and query by entities:
# create entities
my_label = ln.ULabel(name="My universal label").save()
my_project = ln.Project(name="My project label").save()

# annotate
artifact.ulabels.add(my_label)
artifact.projects.add(my_project)

# query
ln.Artifact.filter(ulabels=my_label, projects=my_project).to_dataframe()
This also works for entities imported from modules, for example, ontology terms:
import bionty as bt

# import an entity from a public ontology source, e.g., by name or an ontology ID
hek293 = bt.CellLine.from_source(name="HEK293").save()
hras = bt.Gene.from_source(ensembl_gene_id="ENSG00000174775").save()

# annotate
artifact.cell_lines.add(hek293)
artifact.genes.add(hras)

# query
ln.Artifact.filter(cell_lines=hek293, genes=hras).to_dataframe(
    include=["cell_lines__name", "genes__symbol"]
)
To annotate & query by features:
from datetime import date

# define a feature type and features
sequences = ln.Feature(name="Sequences", is_type=True).save()
gc_content = ln.Feature(name="gc_content", dtype=float, type=sequences).save()
seq_date = ln.Feature(name="seq_date", dtype=date, type=sequences).save()

# annotate
artifact.features.set_values({
    gc_content: 0.55,
    seq_date: date.today(),
})

# query
ln.Artifact.filter(seq_date == date.today()).to_dataframe(include="features")
To query by auto-tracked metadata:
# by storage location and size
ln.Artifact.filter(storage__root=ln.settings.storage.root)
ln.Artifact.filter(size__gt=1e6).to_dataframe()

# by data lineage
ln.Artifact.filter(run=run).to_dataframe()
ln.Artifact.filter(run__transform=transform).to_dataframe()

# include more information in resulting dataframe
ln.Artifact.to_dataframe(include=["run__transform__key", "storage__root"])
Read more: docs.lamin.ai/organize or docs.lamin.ai/query-search
Create records & notes
You can create record types to model metadata for any entity:
# create record types
experiment_type = ln.Record(name="Experiments", is_type=True).save()
sample_type = ln.Record(name="Samples", is_type=True).save()

# create an experiment
experiment1 = ln.Record(
    name="Experiment 1",
    features={seq_date: date.today()},
    type=experiment_type
).save()

# create a sample that links to "Experiment 1" via a feature
experiment = ln.Feature(name="experiment", dtype=experiment_type).save()
sample1 = ln.Record(
    features={gc_content: 0.5, experiment: experiment1},
    type=sample_type
).save()

# export all experiments and all samples
experiment_type.to_dataframe()
sample_type.to_dataframe()
You can save markdown notes as records:
lamin save <topic>/<my-note.md>
Load it.
To load a record back as a markdown file, run:
lamin load https://lamin.ai/laminlabs/lamindata/record/mNDJgWFrkWQVW3ox
Watch a mini video: youtu.be/NRzVQXJaRH8
Read more: docs.lamin.ai/manage-records.
Validate datasets
Here is how you ingest a DataFrame:
import pandas as pd

df = pd.DataFrame({
    "seq_str": ["ACGT", "TGCA"],
    "gc_content": [0.55, 0.54],
    "experiment_note": ["Looks great", "Ok"],
    "seq_date": [date(2025, 10, 24), date(2025, 10, 25)],
})
ln.Artifact.from_dataframe(df, key="my_datasets/sequences.parquet").save()  # no validation
Let's now define a schema that validates the columns of the dataframe against the feature type sequences that we defined above:
ln.Feature(name="seq_str", dtype=str, type=sequences).save()
ln.Feature(name="experiment_note", dtype=str, type=sequences).save()
schema = ln.Schema(itype=sequences).save()
If we pass it from_dataframe(), the resulting artifact is validated and auto-anntotated:
artifact = ln.Artifact.from_dataframe(
    df,
    key="my_datasets/sequences.parquet",
    schema=schema,
).save()
artifact.describe()
You can filter for datasets by schema and then launch distributed queries or batch load distributed datasets. For tables, see: docs.lamin.ai/tables. For arrays, see: docs.lamin.ai/arrays.
Watch a mini video: youtu.be/Ji6E7hTnReQ
To validate and auto-annotate an AnnData, use a feature type for the obs columns and Ensembl gene ids for var:
import anndata as ad
import bionty as bt
import numpy as np
import pandas as pd

# define the schema
cells = ln.Feature(name="Cells", is_type=True).save()
ln.Feature(name="cell_type_by_model", dtype=bt.CellType, type=cells).save()
obs_schema = ln.Schema(itype=cells).save()
var_schema = ln.Schema(itype=bt.Gene.ensembl_gene_id).save()
anndata_schema = ln.Schema(
    otype="AnnData", slots={"obs": obs_schema, "var.T": var_schema}
).save()

# define the AnnData object
adata = ad.AnnData(
    X=np.ones((21, 3)),
    obs=pd.DataFrame({"cell_type_by_model": ["T cell", "B cell", "T cell"] * 7}),
    var=pd.DataFrame(
        index=["ENSG00000153563", "ENSG00000010610", "ENSG00000170458"]
    ),
)

# validate, annotate, and ingest the AnnData object
artifact = ln.Artifact.from_anndata(
    adata,
    key="my_datasets/scrna.h5ad",
    schema=anndata_schema,
).save()
artifact.describe()
To validate a SpatialData or any other array-like dataset, you need to construct a Schema. You can do this by composing simple pandera-style schemas: docs.lamin.ai/curate.
Use branching & versioning
LaminDB versions transforms, artifacts, and collections.
If you edit and run the create_fasta.py script, you'll automatically create a new version of the transform and the sample.fasta artifact.
The edited script.
# create_fasta.py
import lamindb as ln

ln.track()
open("sample.fasta", "w").write(">seq1\nTGCA\n")  # a new sequence
ln.Artifact("sample.fasta", key="sample.fasta", features={"experiment": "Experiment 1"}).save()  # annotate with the new experiment
ln.finish()
artifact_latest = ln.Artifact.get(key="sample.fasta")  # pass version for a previous version: ln.Artifact.get(key="sample.fasta", version="1.0")
artifact_latest.versions.to_dataframe()                # all versions of that artifact
artifact_latest.run.transform.versions.to_dataframe()  # all versions of the transform that created the artifact
If you create a branch and switch to it as in git, you'll create new objects and new versions of objects on it:
lamin switch -c my_branch
To merge a contribution branch into main, run:
lamin switch main  # switch to the main branch
lamin merge my_branch  # merge contribution branch into main
Read more: docs.lamin.ai/manage-changes.
Watch a mini video: youtu.be/rzRwcMj6-fc
Share datasets
To share data in a lineage-aware way, transfer objects from a source database to your default database:
db = ln.DB("laminlabs/lamindata")
artifact = db.Artifact.get(key="example_datasets/mini_immuno/dataset1.h5ad")
artifact.save()
This is zero-copy for the artifact's data in storage. Read more: docs.lamin.ai/transfer.
Manage ontologies
You can use Record to build your ELN & LIMS, your own ontologies, and even a knowledge graph with slow graph queries. If you instead want to build on public biological ontologies: bionty gives you >20 public ontologies so that you don't have to build ontologies for basic biological entities from scratch. For example, the Gene registry was used to validate the ENSG ids in the AnnData object above.
Here is how you import a public ontology into the CellType registry:
import bionty as bt

bt.CellType.import_source()  # import the default ontology
bt.CellType.to_dataframe()   # your extensible cell type ontology in a simple registry
You can then create objects, e.g. for labeling, analogous to ULabel or Project:
t_cell = bt.CellType.get(name="T cell")  # get a T cell label
artifact.cell_types.add(t_cell)          # annotate an artifact
Read more: docs.lamin.ai/manage-ontologies.
Watch a mini video: youtu.be/3vpWjHj3Kw8
Run: HBLXnJc (docs/README.ipynb)
├── uid: HBLXnJcyojww6T00                transform: docs/README.ipynb (0000)
│   started_at: 2026-11-02 14:17:06 UTC  finished_at: 2026-11-02 14:17:08 UTC
│   status: completed
│   branch: main                         space: all
│   created_at: 2026-11-02 14:17:06 UTC  created_by: anonymous
└── environment: XMQGx0j
    │ aiobotocore==3.10.0
    │ aiohappyeyeballs==2.7.1
    │ aiohttp==3.14.5
    │ aioitertools==0.13.0
    │ …
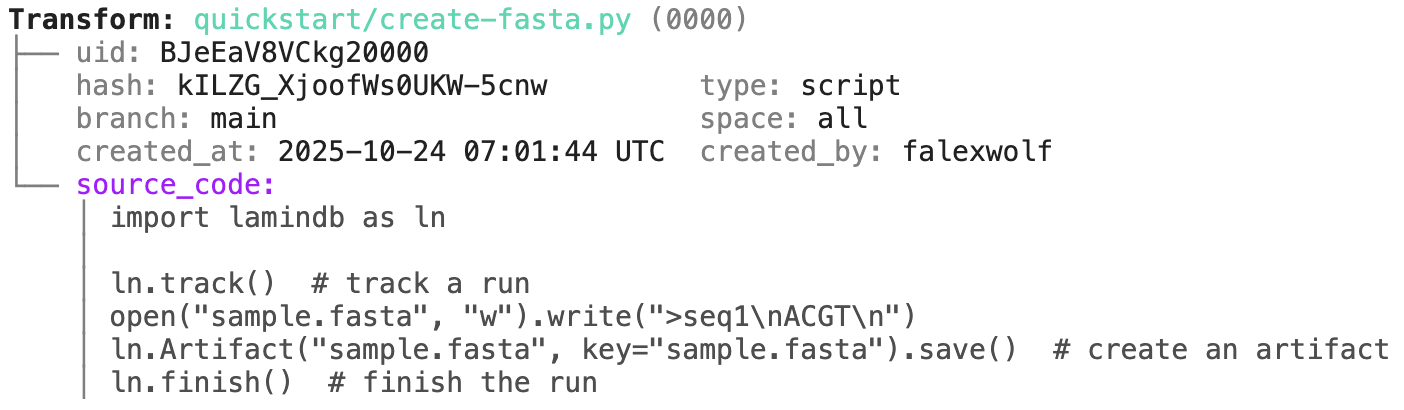
transform.describe() # context of the transform
Transform: docs/README.ipynb (0000) | description: LaminDB: Data management for traceable, multimodal AI ├── uid: BmfhBUrxBHXj0000 │ hash: hclArs0p71QMvPyP4tN5cw type: notebook │ branch: main space: all │ created_at: 2026-11-02 14:17:06 UTC created_by: anonymous └── source_code: │ # %% [markdown] │ # [](https://docs.lamin.ai) [![ … │ # │ # │ # │ # LaminDB is an open-source data management tool that makes it easy to query, tr … │ # Like git, LaminDB runs anywhere and captures relevant context about your work. │ # This includes the data flow through models and analyses, the entities and note … │ # It takes about a minute to install LaminDB and create a database on your lapto … │ # │ # <details> │ # <summary>Why?</summary> │ # │ # 1. Untraceable results cannot be trusted, especially when non-verifiable tasks … │ # 2. Without effective access to multimodal data, models burn tokens or fail ent … │ # 3. Without governing changes to data akin to governing changes to software wit … │ # │ # Especially in life sciences, hard-to-verify tasks are abundant, data formats a … │ # │ # Existing data lakehouses aren't a comprehensive solution. They only address th … │ # │ # </details> │ # │ # <img width="800" alt="lamindb-schematic" src="https://lamin-site-assets.s3.ama … │ # │ # How? │ # │ # - **lineage** → trace results across agent sessions, notebooks, scripts & work … │ # - **lakehouse** → manage datasets in any format (`parquet`, `zarr`, ...) with … │ # - **LIMS & ELN** → unified schema-based records management with support for on … │ …
To track a workflow, decorate a function:
import lamindb as ln

@ln.flow()
def create_fasta(fasta_file: str = "sample.fasta"):
    open(fasta_file, "w").write(">seq1\nACGT\n")    # create dataset
    ln.Artifact(fasta_file, key=fasta_file).save()  # save dataset

if __name__ == "__main__":
    pass
Beyond what you get for scripts & notebooks, this automatically tracks function & CLI params and integrates well with established Python workflow managers: docs.lamin.ai/track. To integrate pipeline managers like Nextflow, see docs.lamin.ai/pipelines.
A richer example.
Here is a re-construction of the project of Schmidt et al. (Science, 2022):
A phenotypic CRISPRa screening result is integrated with scRNA-seq data. Here is the result of the screen input:
You can explore it here.
Annotate & query artifacts
To annotate and query by entities:
# create entities
my_label = ln.ULabel(name="My universal label").save()
my_project = ln.Project(name="My project label").save()

# annotate
artifact.ulabels.add(my_label)
artifact.projects.add(my_project)

# query
ln.Artifact.filter(ulabels=my_label, projects=my_project).to_dataframe()
! tip: pass `type` to map ulabel into a type hierarchy
! tip: pass `type` to map project into a type hierarchy
| uid | key | description | suffix | kind | otype | size | hash | n_files | n_observations | ... | is_latest | is_locked | created_at | branch_id | created_on_id | space_id | storage_id | run_id | schema_id | created_by_id | |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| id | |||||||||||||||||||||
| 1 | 6jkGCL4r8v7WTDY90000 | sample.fasta | None | .fasta | None | None | 11 | 83rEPcAoBHmYiIuyBYrFKg | None | None | ... | True | False | 2026-11-02 14:17:05.761+00:00 | 1 | 1 | 1 | 1 | 1 | None | 1 |
1 rows × 22 columns
This also works for entities imported from modules, for example, ontology terms:
import bionty as bt

# import an entity from a public ontology source, e.g., by name or an ontology ID
hek293 = bt.CellLine.from_source(name="HEK293").save()
hras = bt.Gene.from_source(ensembl_gene_id="ENSG00000174775").save()

# annotate
artifact.cell_lines.add(hek293)
artifact.genes.add(hras)

# query
ln.Artifact.filter(cell_lines=hek293, genes=hras).to_dataframe(
    include=["cell_lines__name", "genes__symbol"]
)
✓ created 1 CellLine record from Bionty matching name: 'HEK293'
✓ created 1 Organism record from Bionty matching ontology_id: 'NCBITaxon:9606'
✓ created 1 Gene record from Bionty matching ensembl_gene_id: 'ENSG00000174775'
| uid | key | cell_lines__name | genes__symbol | |
|---|---|---|---|---|
| id | ||||
| 1 | 6jkGCL4r8v7WTDY90000 | sample.fasta | {HEK293} | {HRAS} |
To annotate & query by features:
from datetime import date

# define a feature type and features
sequences = ln.Feature(name="Sequences", is_type=True).save()
gc_content = ln.Feature(name="gc_content", dtype=float, type=sequences).save()
seq_date = ln.Feature(name="seq_date", dtype=date, type=sequences).save()

# annotate
artifact.features.set_values({
    gc_content: 0.55,
    seq_date: date.today(),
})

# query
ln.Artifact.filter(seq_date == date.today()).to_dataframe(include="features")
! tip: pass `type` to map feature into a type hierarchy
| uid | key | gc_content | seq_date | |
|---|---|---|---|---|
| id | ||||
| 1 | 6jkGCL4r8v7WTDY90000 | sample.fasta | 0.55 | 2026-11-02 |
To query by auto-tracked metadata:
# by storage location and size
ln.Artifact.filter(storage__root=ln.settings.storage.root)
ln.Artifact.filter(size__gt=1e6).to_dataframe()

# by data lineage
ln.Artifact.filter(run=run).to_dataframe()
ln.Artifact.filter(run__transform=transform).to_dataframe()

# include more information in resulting dataframe
ln.Artifact.to_dataframe(include=["run__transform__key", "storage__root"])
| uid | key | run__transform__key | storage__root | |
|---|---|---|---|---|
| id | ||||
| 1 | 6jkGCL4r8v7WTDY90000 | sample.fasta | docs/README.ipynb | /home/runner/work/lamindb/lamindb/storage |
Read more: docs.lamin.ai/organize or docs.lamin.ai/query-search
Create records & notes
You can create record types to model metadata for any entity:
# create record types
experiment_type = ln.Record(name="Experiments", is_type=True).save()
sample_type = ln.Record(name="Samples", is_type=True).save()

# create an experiment
experiment1 = ln.Record(
    name="Experiment 1",
    features={seq_date: date.today()},
    type=experiment_type
).save()

# create a sample that links to "Experiment 1" via a feature
experiment = ln.Feature(name="experiment", dtype=experiment_type).save()
sample1 = ln.Record(
    features={gc_content: 0.5, experiment: experiment1},
    type=sample_type
).save()

# export all experiments and all samples
experiment_type.to_dataframe()
sample_type.to_dataframe()
! tip: pass `type` to map record into a type hierarchy
! tip: pass `type` to map record into a type hierarchy
! tip: pass `type` to map feature into a type hierarchy
→ exporting 1 records of 'Experiments'
→ exporting 1 records of 'Samples'
| experiment | gc_content | __lamindb_record_uid__ | __lamindb_record_name__ | |
|---|---|---|---|---|
| __lamindb_record_id__ | ||||
| 4 | Experiment 1 | 0.5 | yhl0zJlldYEnWDKp | None |
You can save markdown notes as records:
lamin save <topic>/<my-note.md>
Load it.
To load a record back as a markdown file, run:
lamin load https://lamin.ai/laminlabs/lamindata/record/mNDJgWFrkWQVW3ox
Watch a mini video: youtu.be/NRzVQXJaRH8
Read more: docs.lamin.ai/manage-records.
Validate datasets
Here is how you ingest a DataFrame:
import pandas as pd

df = pd.DataFrame({
    "seq_str": ["ACGT", "TGCA"],
    "gc_content": [0.55, 0.54],
    "experiment_note": ["Looks great", "Ok"],
    "seq_date": [date(2025, 10, 24), date(2025, 10, 25)],
})
ln.Artifact.from_dataframe(df, key="my_datasets/sequences.parquet").save()  # no validation
Artifact(uid='eVGzEEkpGOIkNpHy0000', key='my_datasets/sequences.parquet', description=None, suffix='.parquet', kind='dataset', otype='DataFrame', size=3290, hash='lsS0KCvEUfy46pY1OxBnXA', n_files=None, n_observations=2, extra_data=None, branch_id=1, created_on_id=1, space_id=1, storage_id=1, run_id=None, schema_id=None, created_by_id=1, created_at=2026-11-02 14:17:16 UTC, is_locked=False, version_tag=None, is_latest=True)
Let’s now define a schema that validates the columns of the dataframe against the feature type sequences that we defined above:
ln.Feature(name="seq_str", dtype=str, type=sequences).save()
ln.Feature(name="experiment_note", dtype=str, type=sequences).save()
schema = ln.Schema(itype=sequences).save()
If we pass it from_dataframe(), the resulting artifact is validated and auto-anntotated:
artifact = ln.Artifact.from_dataframe(
    df,
    key="my_datasets/sequences.parquet",
    schema=schema,
).save()
artifact.describe()
→ returning artifact with same hash: Artifact(uid='eVGzEEkpGOIkNpHy0000', key='my_datasets/sequences.parquet', description=None, suffix='.parquet', kind='dataset', otype='DataFrame', size=3290, hash='lsS0KCvEUfy46pY1OxBnXA', n_files=None, n_observations=2, extra_data=None, branch_id=1, created_on_id=1, space_id=1, storage_id=1, run_id=None, schema_id=None, created_by_id=1, created_at=2026-11-02 14:17:16 UTC, is_locked=False, version_tag=None, is_latest=True); to track this artifact as an input, use: ln.Artifact.get()
→ loading artifact into memory for validation
Artifact: my_datasets/sequences.parquet (0000)
├── uid: eVGzEEkpGOIkNpHy0000  kind: dataset
│   otype: DataFrame           hash: lsS0KCvEUfy46pY1OxBnXA
│   size: 3.2 KB               branch: main
│   space: all                 created_at: 2026-11-02 14:17:16 UTC
│   created_by: anonymous      n_observations: 2
│   schema: wVHoOve
├── storage/path: /home/runner/work/lamindb/lamindb/storage/.lamindb/eVGzEEkpGOIkNpHy0000.parquet
└── Dataset features
    └── columns (4 Feature[Rne0aQToA…
        experiment_note                str
        gc_content                     float
        seq_date                       date
        seq_str                        str
You can filter for datasets by schema and then launch distributed queries or batch load distributed datasets. For tables, see: docs.lamin.ai/tables. For arrays, see: docs.lamin.ai/arrays.
Watch a mini video: youtu.be/Ji6E7hTnReQ
To validate and auto-annotate an AnnData, use a feature type for the obs columns and Ensembl gene ids for var:
import anndata as ad
import bionty as bt
import numpy as np
import pandas as pd

# define the schema
cells = ln.Feature(name="Cells", is_type=True).save()
ln.Feature(name="cell_type_by_model", dtype=bt.CellType, type=cells).save()
obs_schema = ln.Schema(itype=cells).save()
var_schema = ln.Schema(itype=bt.Gene.ensembl_gene_id).save()
anndata_schema = ln.Schema(
    otype="AnnData", slots={"obs": obs_schema, "var.T": var_schema}
).save()

# define the AnnData object
adata = ad.AnnData(
    X=np.ones((21, 3)),
    obs=pd.DataFrame({"cell_type_by_model": ["T cell", "B cell", "T cell"] * 7}),
    var=pd.DataFrame(
        index=["ENSG00000153563", "ENSG00000010610", "ENSG00000170458"]
    ),
)

# validate, annotate, and ingest the AnnData object
artifact = ln.Artifact.from_anndata(
    adata,
    key="my_datasets/scrna.h5ad",
    schema=anndata_schema,
).save()
artifact.describe()
! tip: pass `type` to map feature into a type hierarchy
→ loading artifact into memory for validation
/opt/hostedtoolcache/Python/3.14.9/x64/lib/python3.14/functools.py:982: ImplicitModificationWarning: Transforming to str index.
  return dispatch(args[0].__class__)(*args, **kw)
/opt/hostedtoolcache/Python/3.14.9/x64/lib/python3.14/re/_compiler.py:320: RuntimeWarning: coroutine '_wait_for_close' was never awaited
  break
RuntimeWarning: Enable tracemalloc to get the object allocation traceback
✓ added 2 records from_public with bionty.CellType for "cell_type_by_model": 'T cell', 'B cell'
✓ added 3 records from_public with bionty.Gene for "columns": 'ENSG00000153563', 'ENSG00000010610', 'ENSG00000170458'
Artifact: my_datasets/scrna.h5ad (0000)
├── uid: sXshiZrji4nkdQpG0000  kind: dataset
│   otype: AnnData             hash: O2ePNFFY9txr66huIosUng
│   size: 22.0 KB              branch: main
│   space: all                 created_at: 2026-11-02 14:17:20 UTC
│   created_by: anonymous      n_observations: 21
│   schema: HCaB0zc
├── storage/path: /home/runner/work/lamindb/lamindb/storage/.lamindb/sXshiZrji4nkdQpG0000.h5ad
├── Dataset features
│   ├── obs (1 Feature[xcM955jzl97N])
│   │   cell_type_by_model             bionty.CellType                      B cell, T cell
│   └── var.T (3 bionty.Gene.ensembl…
│       CD14                           num
│       CD4                            num
│       CD8A                           num
└── Entities
    └── .cell_types                    bionty.CellType                      T cell, B cell
To validate a SpatialData or any other array-like dataset, you need to construct a Schema. You can do this by composing simple pandera-style schemas: docs.lamin.ai/curate.
Use branching & versioning
LaminDB versions transforms, artifacts, and collections.
If you edit and run the create_fasta.py script, you’ll automatically create a new version of the transform and the sample.fasta artifact.
The edited script.
# create_fasta.py
import lamindb as ln

ln.track()
open("sample.fasta", "w").write(">seq1\nTGCA\n")  # a new sequence
ln.Artifact("sample.fasta", key="sample.fasta", features={"experiment": "Experiment 1"}).save()  # annotate with the new experiment
ln.finish()
→ found notebook docs/README.ipynb, making new version -- anticipating changes
→ created Transform('BmfhBUrxBHXj0001', key='docs/README.ipynb'), started new Run('lPDYF2sPdmX3CkmC') at 2026-11-02 14:17:20 UTC
• tip: to identify the notebook across renames, pass the uid: ln.track("BmfhBUrxBHXj")
→ creating new artifact version for key 'sample.fasta' in storage '/home/runner/work/lamindb/lamindb/storage'
! cells [(8, 10), (22, 24)] were not run consecutively
→ returning artifact with same hash: Artifact(uid='yBjw53iCABRo0yxR0000', key=None, description='Report of run HBLXnJcyojww6T00', suffix='.html', kind='__lamindb_run__', otype=None, size=361091, hash='apf6RBJ_qMEGp1HpDvHm7Q', n_files=None, n_observations=None, extra_data=None, branch_id=1, created_on_id=1, space_id=1, storage_id=1, run_id=None, schema_id=None, created_by_id=1, created_at=2026-11-02 14:17:08 UTC, is_locked=False, version_tag=None, is_latest=True); to track this artifact as an input, use: ln.Artifact.get()
! run was not set on Artifact(uid='yBjw53iCABRo0yxR0000', key=None, description='Report of run HBLXnJcyojww6T00', suffix='.html', kind='__lamindb_run__', otype=None, size=361091, hash='apf6RBJ_qMEGp1HpDvHm7Q', n_files=None, n_observations=None, extra_data=None, branch_id=1, created_on_id=1, space_id=1, storage_id=1, run_id=None, schema_id=None, created_by_id=1, created_at=2026-11-02 14:17:08 UTC, is_locked=False, version_tag=None, is_latest=True), setting to current run
! updated description from Report of run HBLXnJcyojww6T00 to Report of run lPDYF2sPdmX3CkmC
! returning transform with same hash & key: Transform(uid='BmfhBUrxBHXj0000', key='docs/README.ipynb', description='LaminDB: Data management for traceable, multimodal AI', kind='notebook', hash='hclArs0p71QMvPyP4tN5cw', reference=None, reference_type=None, environment=None, plan=None, branch_id=1, created_on_id=1, space_id=1, run_id=None, created_by_id=1, created_at=2026-11-02 14:17:06 UTC, is_locked=False, version_tag=None, is_latest=False)
! run was not set on Transform(uid='BmfhBUrxBHXj0000', key='docs/README.ipynb', description='LaminDB: Data management for traceable, multimodal AI', kind='notebook', hash='hclArs0p71QMvPyP4tN5cw', reference=None, reference_type=None, environment=None, plan=None, branch_id=1, created_on_id=1, space_id=1, run_id=None, created_by_id=1, created_at=2026-11-02 14:17:06 UTC, is_locked=False, version_tag=None, is_latest=False), setting to current run
• new latest Transform version is: BmfhBUrxBHXj0000
→ finished Run('lPDYF2sPdmX3CkmC') after 1s at 2026-11-02 14:17:21 UTC
artifact_latest = ln.Artifact.get(key="sample.fasta")  # pass version for a previous version: ln.Artifact.get(key="sample.fasta", version="1.0")
artifact_latest.versions.to_dataframe()                # all versions of that artifact
artifact_latest.run.transform.versions.to_dataframe()  # all versions of the transform that created the artifact
| uid | key | description | kind | source_code | hash | reference | reference_type | version_tag | is_latest | is_locked | created_at | branch_id | created_on_id | space_id | environment_id | plan_id | run_id | created_by_id | |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| id | |||||||||||||||||||
| 1 | BmfhBUrxBHXj0000 | docs/README.ipynb | LaminDB: Data management for traceable, multim... | notebook | # %% [markdown]\n# [ # import the default ontology
bt.CellType.to_dataframe() # your extensible cell type ontology in a simple registry
✓ import is completed!
! truncated query result to limit=20 CellType objects
| uid | name | ontology_id | abbr | synonyms | description | is_locked | created_at | branch_id | created_on_id | space_id | created_by_id | run_id | source_id | |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| id | ||||||||||||||
| 3545 | 1ChUsEzDZXWW4B | beam B cell, human | CL:7770006 | None | nan | A Trabecular Meshwork Cell Within The Eye'S Tr... | False | 2026-11-02 14:17:29.075+00:00 | 1 | 1 | 1 | 1 | None | 26 |
| 3544 | 5xoxfxIf7WrLdU | beam cell | CL:7770005 | None | nan | A Trabecular Meshwork Cell That Is Part Of The... | False | 2026-11-02 14:17:29.075+00:00 | 1 | 1 | 1 | 1 | None | 26 |
| 3543 | 2j5mhhFoV2vBDV | suprabasal cell | CL:7770004 | None | nan | An Epithelial Cell That Resides In The Layer(S... | False | 2026-11-02 14:17:29.075+00:00 | 1 | 1 | 1 | 1 | None | 26 |
| 3542 | RBCFqAmkM1oaaZ | beam A cell | CL:7770003 | None | nan | A Beam Cell Within The Eye'S Trabecular Meshwo... | False | 2026-11-02 14:17:29.075+00:00 | 1 | 1 | 1 | 1 | None | 26 |
| 3541 | 79Ow7BGPRP018I | juxtacanalicular tissue cell | CL:7770002 | None | nan | A Trabecular Meshwork Cell Of The Juxtacanalic... | False | 2026-11-02 14:17:29.075+00:00 | 1 | 1 | 1 | 1 | None | 26 |
| 3540 | 4qJMS0d5FyIXQK | OB FRMD7 GABA GABAergic neuron (Primate) | CL:4310148 | None | OB FRMD7 GABA | A Gabaergic Neuron Of The Primates Brain. Thes... | False | 2026-11-02 14:17:29.075+00:00 | 1 | 1 | 1 | 1 | None | 26 |
| 3539 | 6iU1Q2FIIkrgND | OB Dopa-GABA OB-Dopa-GABA (Primate) | CL:4310147 | None | OB Dopa-GABA | A Ob-Dopa-Gaba Of The Primates Brain. These Ce... | False | 2026-11-02 14:17:29.075+00:00 | 1 | 1 | 1 | 1 | None | 26 |
| 3538 | 100qUn3IH1Ksw2 | AMY-SLEA-BNST GABA GABAergic interneuron (Prim... | CL:4310146 | None | AMY-SLEA-BNST GABA | A Gabaergic Interneuron Of The Primates Brain.... | False | 2026-11-02 14:17:29.075+00:00 | 1 | 1 | 1 | 1 | None | 26 |
| 3537 | QJ8929f49Ncfrf | AMY-SLEA-BNST D1 GABA GABAergic interneuron (P... | CL:4310145 | None | AMY-SLEA-BNST D1 GABA | A Gabaergic Interneuron Of The Primates Brain.... | False | 2026-11-02 14:17:29.075+00:00 | 1 | 1 | 1 | 1 | None | 26 |
| 3536 | 2RruqlADchF4D3 | VTR-HTH Glut glutamatergic neuron of the basal... | CL:4310144 | None | F M Glut|VTR-HTH Glut | A Glutamatergic Neuron Of The Basal Ganglia Of... | False | 2026-11-02 14:17:29.075+00:00 | 1 | 1 | 1 | 1 | None | 26 |
| 3535 | 44qrwytpXARNMz | ZI-HTH GABA GABAergic interneuron (Primate) | CL:4310143 | None | ZI-HTH GABA | A Gabaergic Interneuron Of The Primates Brain.... | False | 2026-11-02 14:17:29.075+00:00 | 1 | 1 | 1 | 1 | None | 26 |
| 3534 | 3dVBqPp88IUIib | STRv D2 MSN nucleus accumbens shell and olfact... | CL:4310138 | None | STRv D2 MSN|D2-Shell/OT | A Nucleus Accumbens Shell And Olfactory Tuberc... | False | 2026-11-02 14:17:29.075+00:00 | 1 | 1 | 1 | 1 | None | 26 |
| 3533 | 4RRtGKe1oGoVGV | STRv D1 NUDAP MSN D1-NUDAP medium spiny neuron... | CL:4310137 | None | D1-NUDAP|STRv D1 NUDAP MSN | A D1-Nudap Medium Spiny Neuron Of The Primates... | False | 2026-11-02 14:17:29.075+00:00 | 1 | 1 | 1 | 1 | None | 26 |
| 3532 | 1Tw4GET7C0W2Az | STRv D1 MSN nucleus accumbens shell and olfact... | CL:4310136 | None | D1-Shell/OT|STRv D1 MSN | A Nucleus Accumbens Shell And Olfactory Tuberc... | False | 2026-11-02 14:17:29.075+00:00 | 1 | 1 | 1 | 1 | None | 26 |
| 3531 | 3taUBSHOL3ffx3 | STR Cholinergic GABA striatal cholinergic-GABA... | CL:4310135 | None | STR Cholinergic GABA | A Striatal Cholinergic-Gabaergic Neuron Of The... | False | 2026-11-02 14:17:29.075+00:00 | 1 | 1 | 1 | 1 | None | 26 |
| 3530 | 2OzOl5s6HeWYYM | STRd D2 Striosome MSN striosomal D2 medium spi... | CL:4310134 | None | D2-Striosome|STRd D2 Striosome MSN | A Striosomal D2 Medium Spiny Neuron Of The Pri... | False | 2026-11-02 14:17:29.075+00:00 | 1 | 1 | 1 | 1 | None | 26 |
| 3529 | 3ZypczMtxf4KQu | STRd D2 StrioMat Hybrid MSN indirect pathway m... | CL:4310133 | None | STRd D2 StrioMat Hybrid MSN | A Indirect Pathway Medium Spiny Neuron Of The ... | False | 2026-11-02 14:17:29.075+00:00 | 1 | 1 | 1 | 1 | None | 26 |
| 3528 | 2Mk5r9Xsi24yLc | STRd D2 Matrix MSN matrix D2 medium spiny neur... | CL:4310132 | None | D2-Matrix|STRd D2 Matrix MSN | A Matrix D2 Medium Spiny Neuron Of The Primate... | False | 2026-11-02 14:17:29.075+00:00 | 1 | 1 | 1 | 1 | None | 26 |
| 3527 | 5e4cn19DcnuNH0 | STR D1D2 Hybrid MSN D1/D2-hybrid medium spiny ... | CL:4310131 | None | STR D1D2 Hybrid MSN|D1/D2 Hybrid | A D1/D2-Hybrid Medium Spiny Neuron Of The Prim... | False | 2026-11-02 14:17:29.075+00:00 | 1 | 1 | 1 | 1 | None | 26 |
| 3526 | 67anmsVZv7HmGa | STRd D1 Striosome MSN striosomal D1 medium spi... | CL:4310130 | None | D1-Striosome|STRd D1 Striosome MSN | A Striosomal D1 Medium Spiny Neuron Of The Pri... | False | 2026-11-02 14:17:29.075+00:00 | 1 | 1 | 1 | 1 | None | 26 |
You can then create objects, e.g. for labeling, analogous to ULabel or Project:
t_cell = bt.CellType.get(name="T cell")  # get a T cell label
artifact.cell_types.add(t_cell)          # annotate an artifact
Read more: docs.lamin.ai/manage-ontologies.
Watch a mini video: youtu.be/3vpWjHj3Kw8